AI modelsSeptember 25, 2026
4
🌱
Liquid AI Triples VLM Decoding Speed
Liquid AI ships DSpark: 3.13x faster decoding for vision-language models.
#Liquid AI#Speculative Decoding#VLM#Inference#Open Weights
🔥 What happened
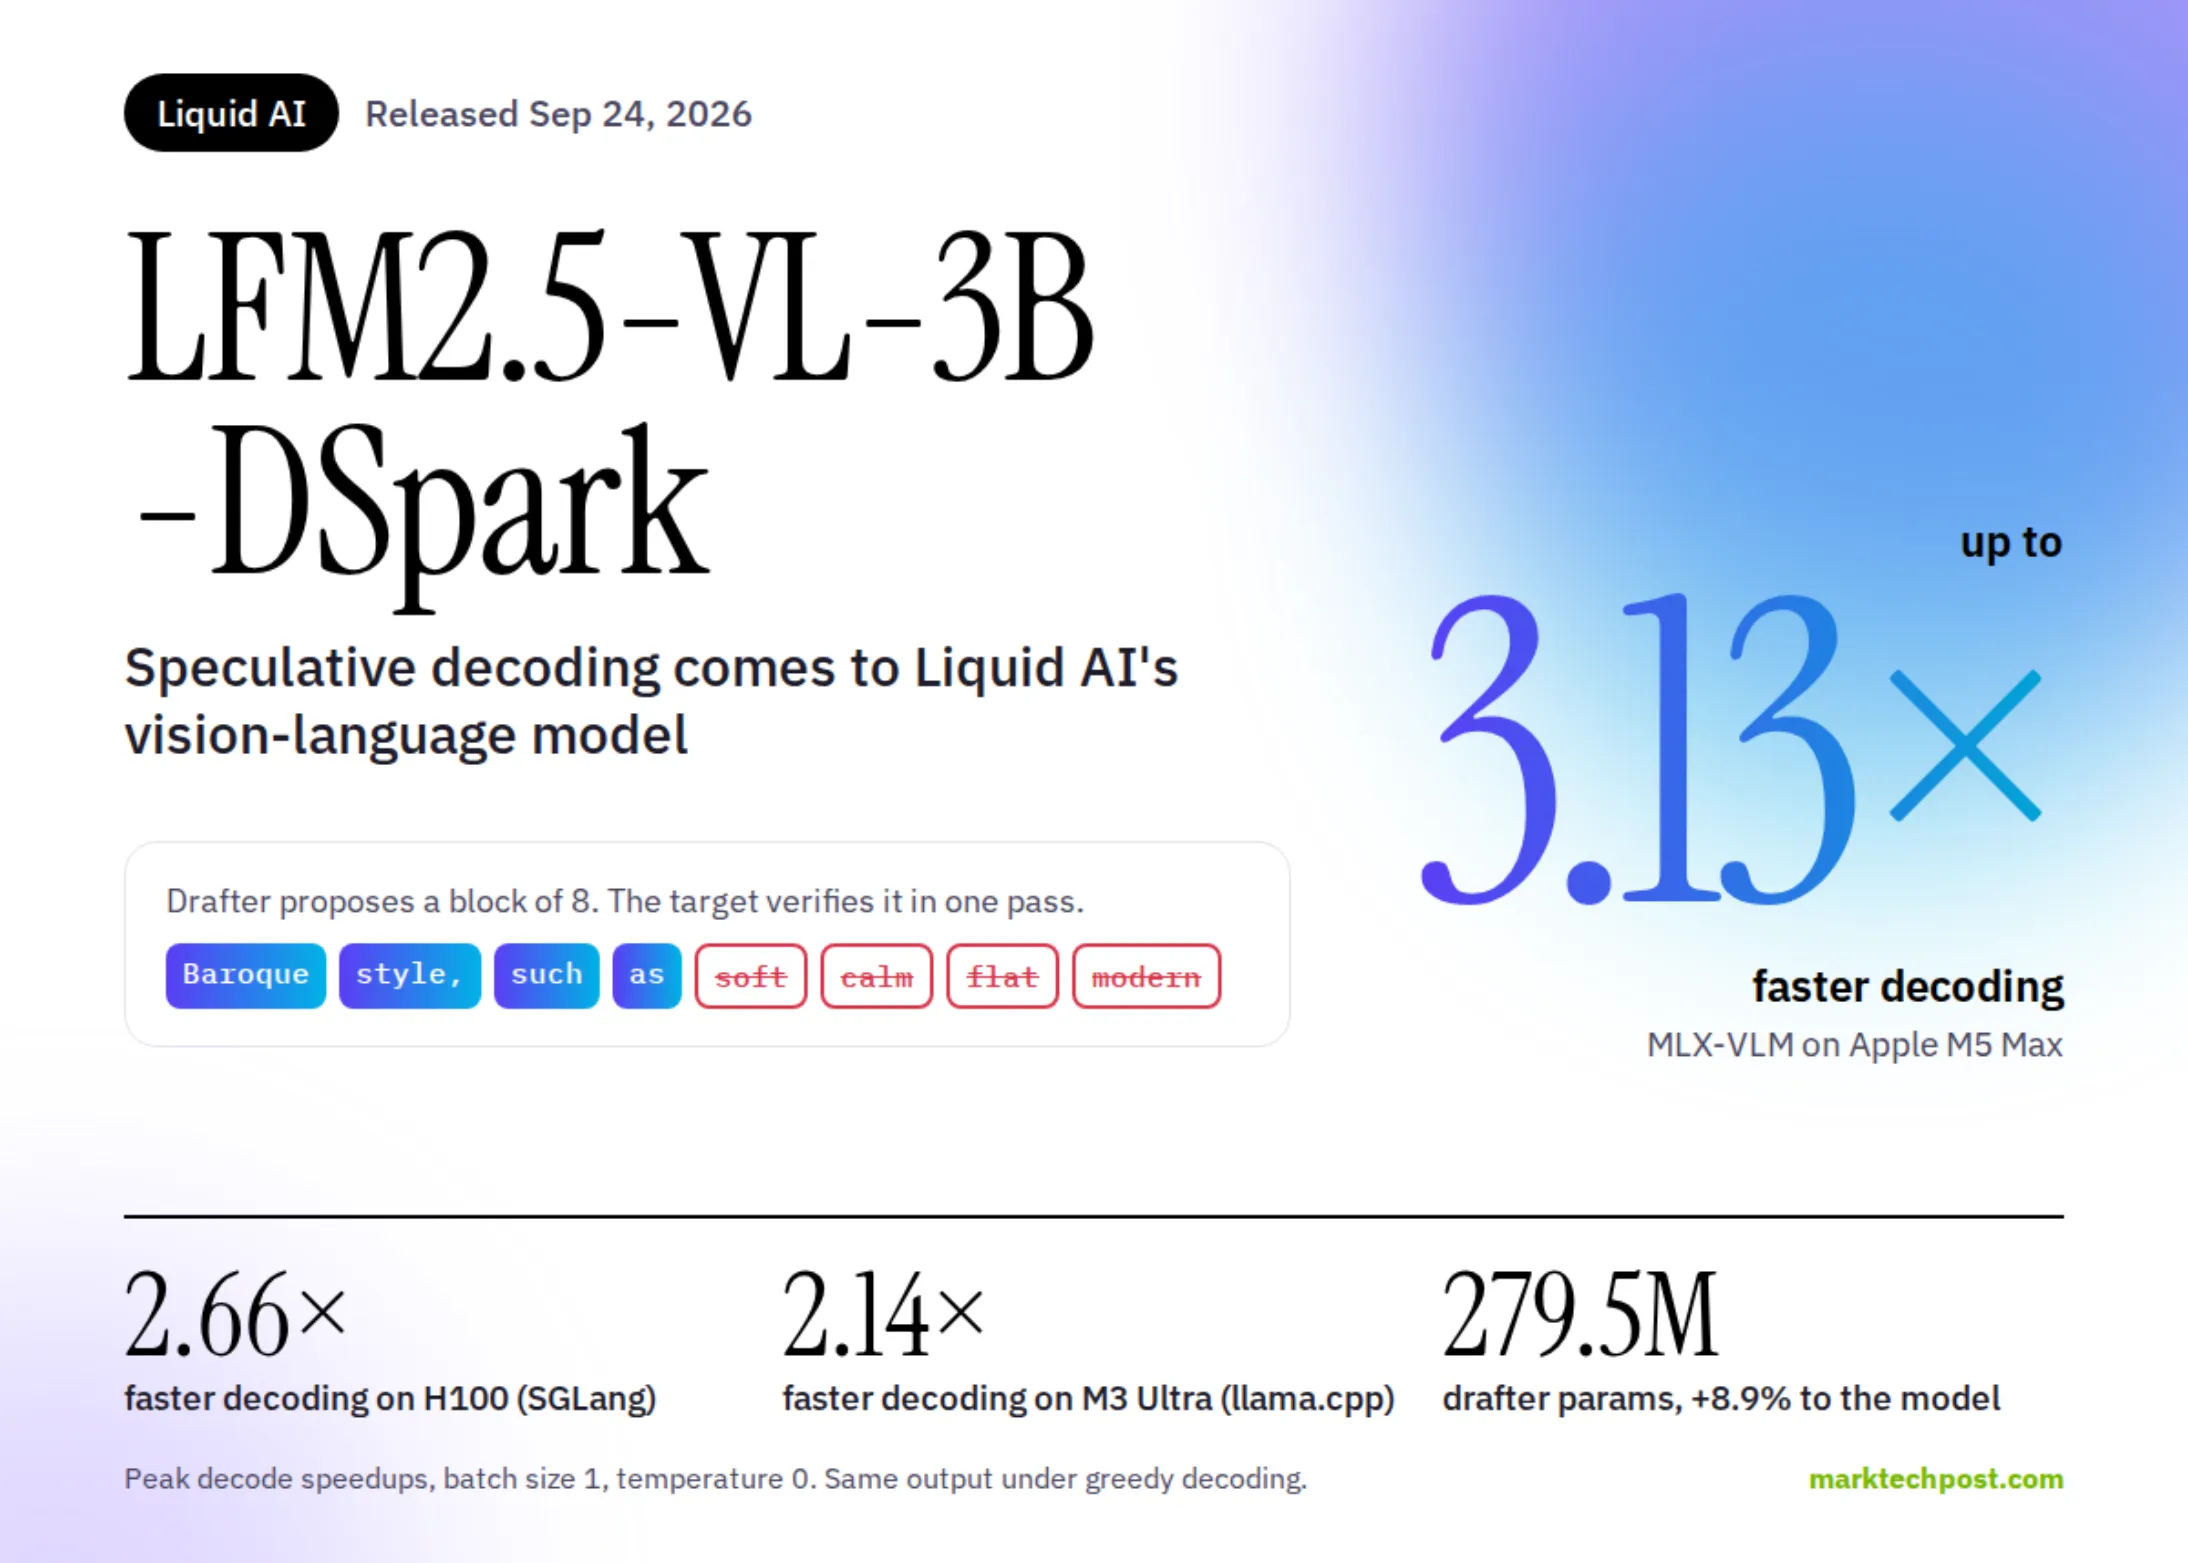
Liquid AI dropped LFM2.5-VL-3B-DSpark, a speculative-decoding drafter with just 280M parameters that accelerates its LFM2.5-VL-3B vision-language model. Decoding gets up to 3.13x faster on Apple silicon and 2.66x on an H100. Weights are live on Hugging Face day one, with support in SGLang, MLX-VLM, and llama.cpp.
💡 Why it matters
The drafter adds only 8.9% parameters and produces bit-identical output under greedy decoding — free speedup, right? Not quite. Prefill and image encoding stay untouched, so end-to-end gains on edge devices collapse to 1.56x. Amdahl's law is undefeated.
⚡ Our take
Clean engineering, but that license is a trap: commercial use only under $10M revenue. Fine for startups, a dealbreaker for everyone else.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.