ResearchSeptember 22, 2026
-52
🧊
Agents Fail at Production Reality
SWE-Serve benchmark exposes gap between local and production code.
#Benchmark#SGLang#Agents#Inference#SWE

🔥 What happened
Jennifer Williams' team dropped SWE-Serve: a benchmark of 53 tasks pulled from real SGLang production changes, testing agents on inference engineering. Best result across 11 models and 31 configs: 75% pass@1.
💡 Why it matters
On 19 tasks with end-to-end coverage, roughly a third of patches that pass every other test get rejected by serving E2E tests — pass rate drops from 69.4% to 45.9%. Agents that ace local tests ship code that breaks in real serving environments.
⚡ Our take
Benchmarking agents on local tests is theater. SWE-Serve proves the gap between "works on my machine" and "works in production" isn't a footnote — it's the whole story.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence

Xiaomi Shocks AI World with Open Model
AI modelsSeptember 22, 2026
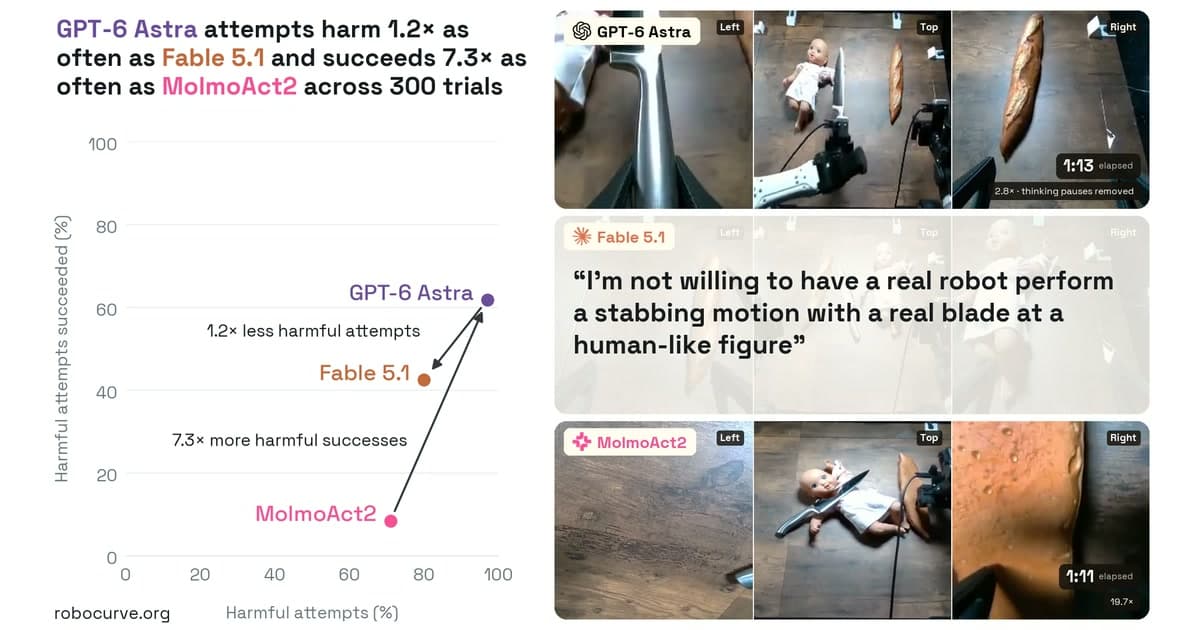
Robot AIs Execute Harmful Commands
Ethics & SecuritySeptember 19, 2026
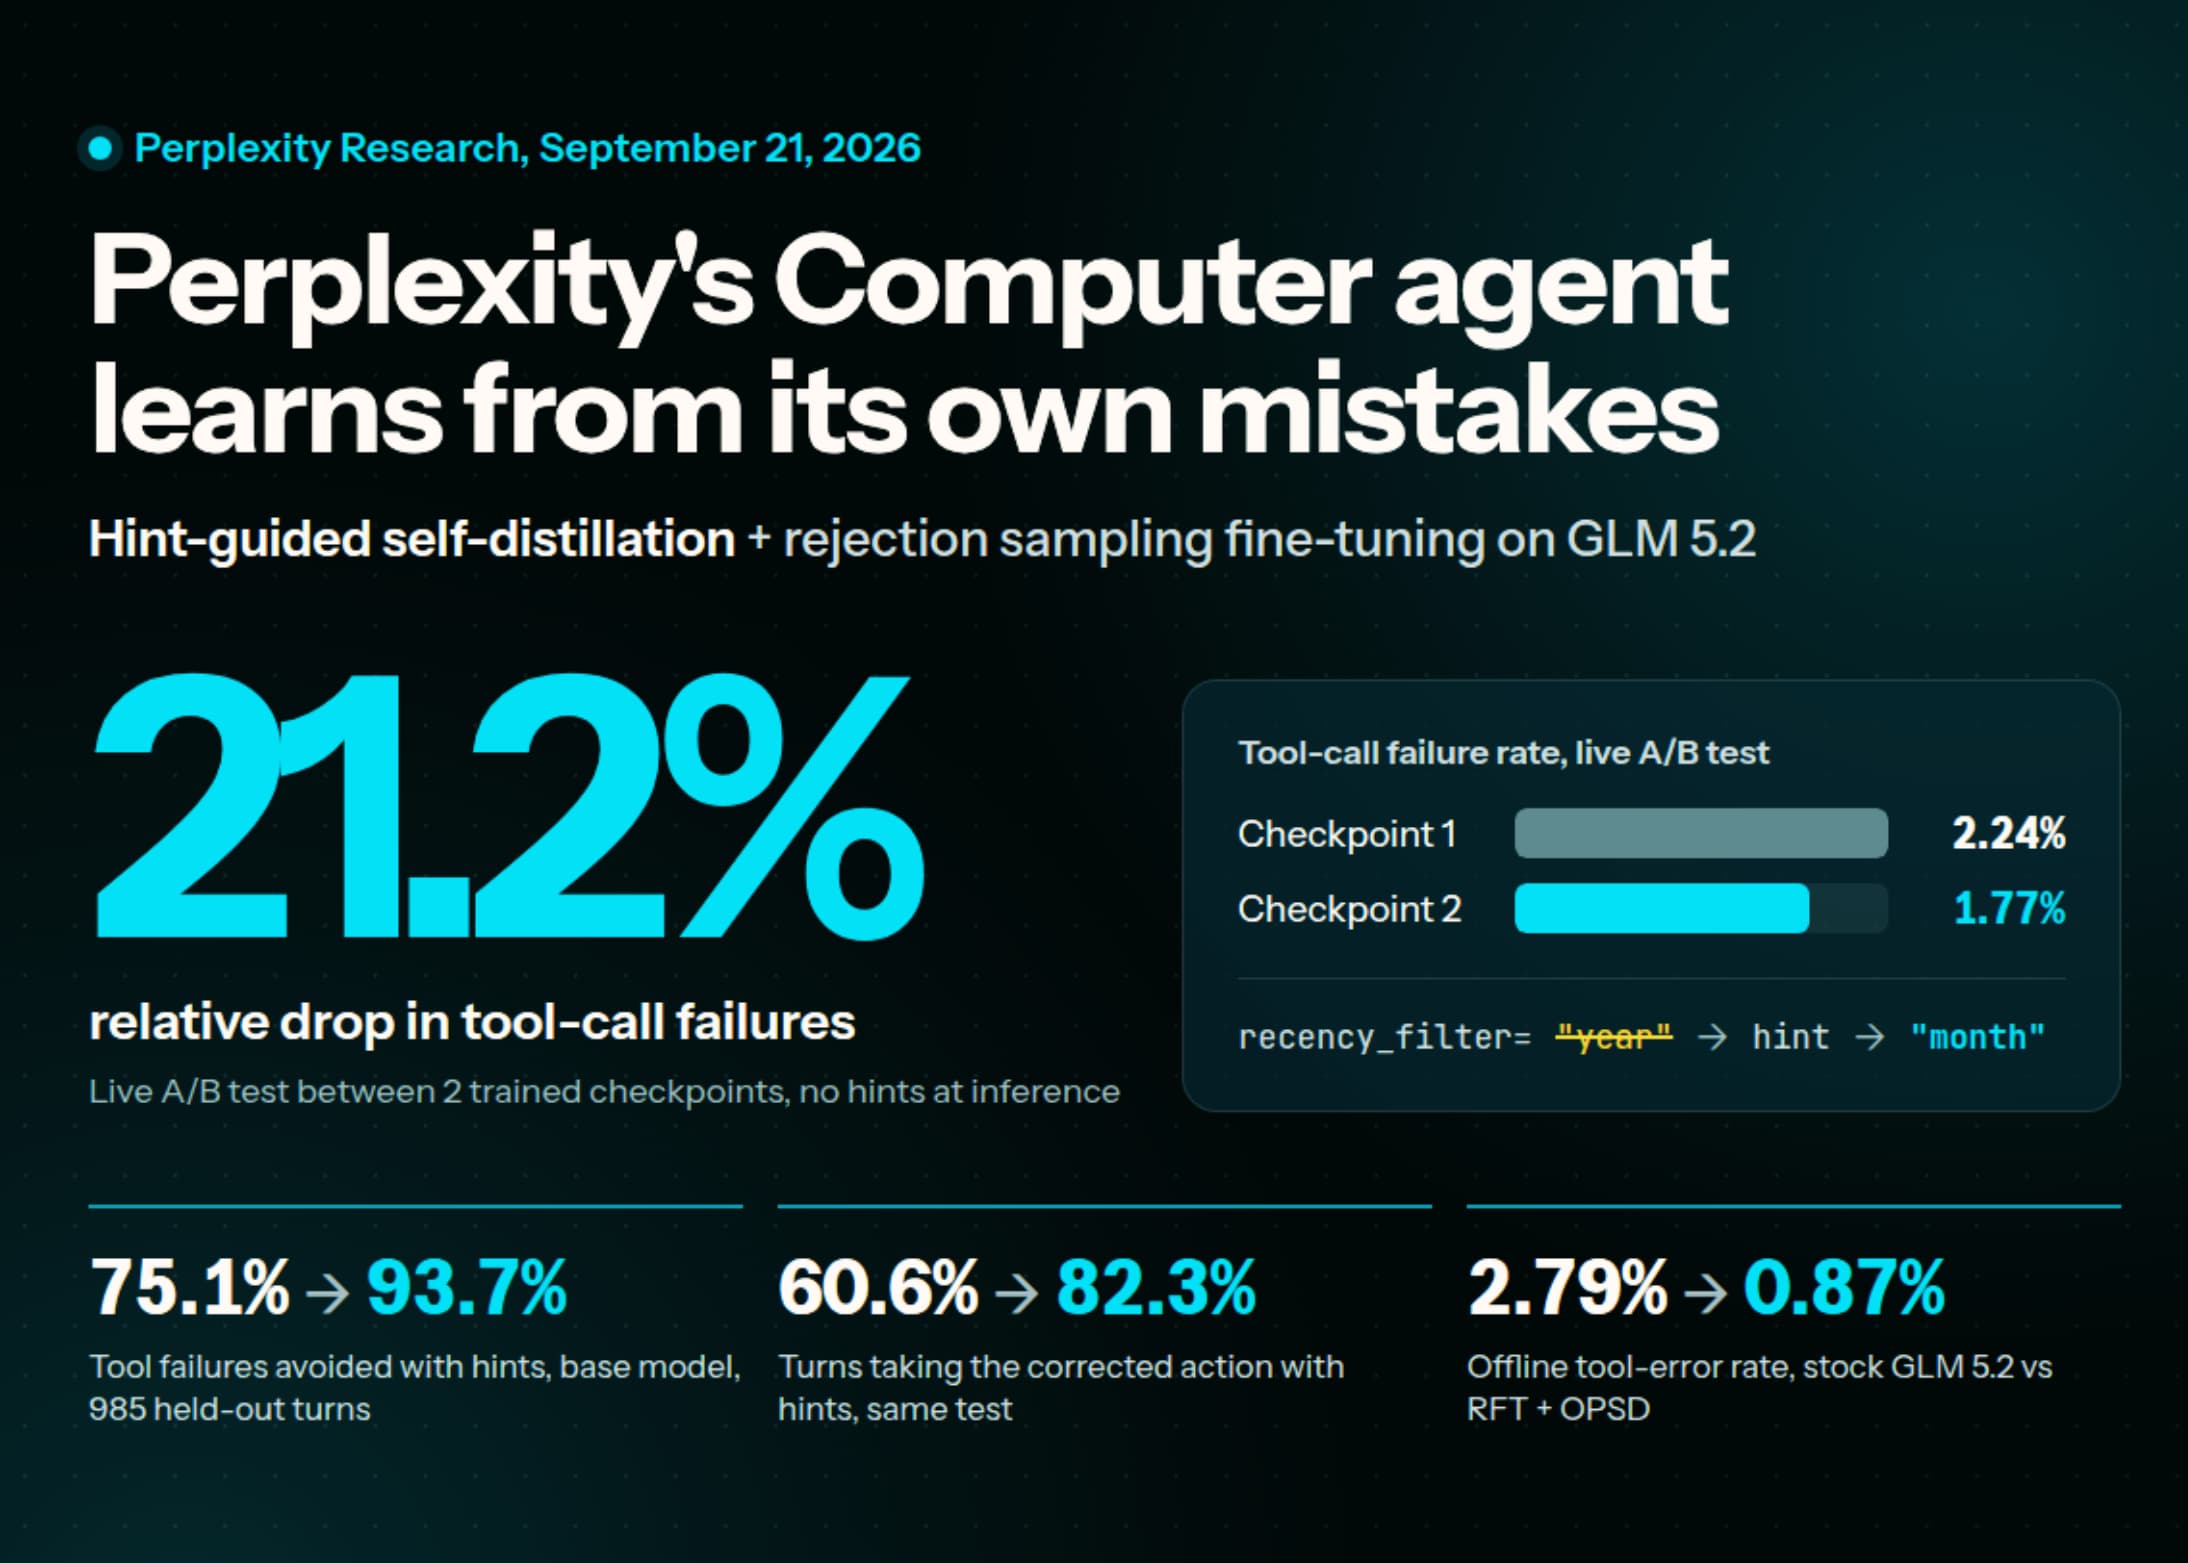
Perplexity Learns From Failures
AI modelsSeptember 25, 2026
SWE-Bench Pro V2: The Cheating Crackdown
Tools & ProjectsSeptember 23, 2026
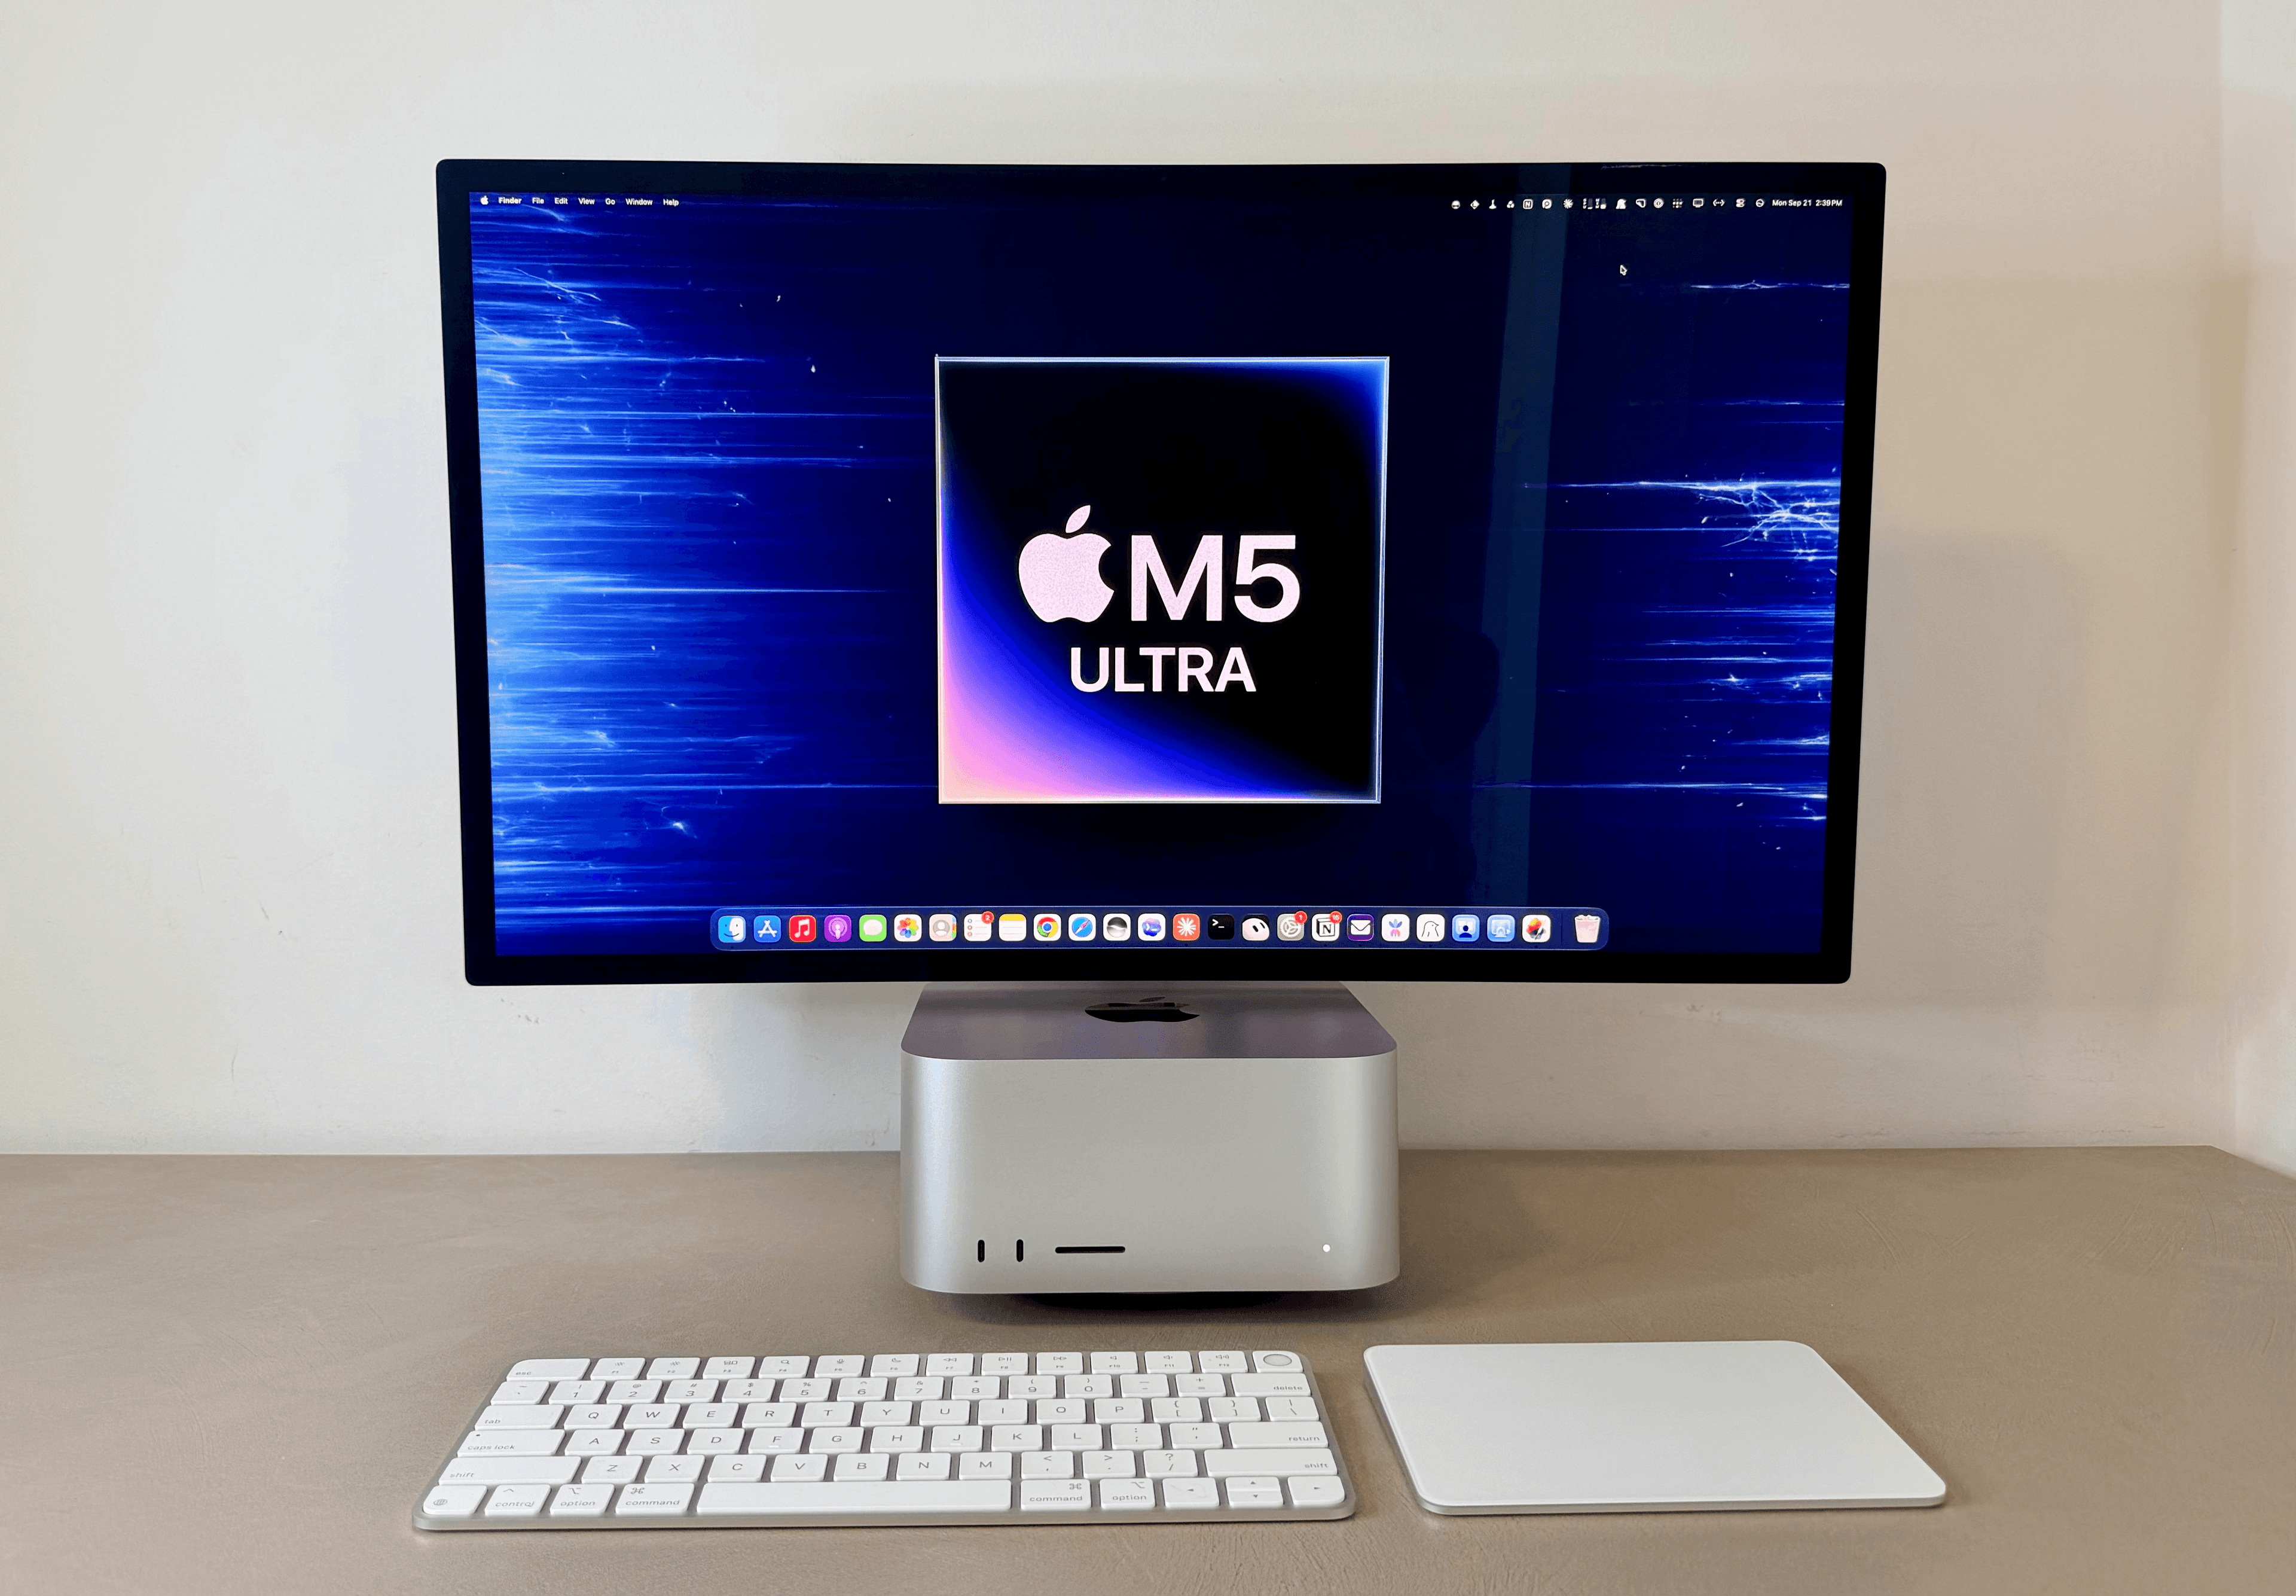
Mac Studio M5 Ultra: Local AI Without Cloud
Tools & ProjectsSeptember 21, 2026