ResearchSeptember 24, 2026
17
🌱
Qwen Spins Up 3,300 RL Worlds for Cents
Qwen trains agents on 3,300 generated environments, raising the score from 0.20 to 0.82.
#Qwen#Agentic RL#Reinforcement Learning#Training Environments#arXiv
🔥 What happened
Qwen's team flipped the pipeline: solve a math model first, then render it into a full agentic environment. The result: 3,300 RL worlds at a few cents apiece.
💡 Why it matters
Qwen3.6-35B-A3B jumps from 0.204 to 0.815 mean agentic score — and beats Qwen3.7-Max on E-Commerce Bench. The paper's kicker: most of the learnable gap sits in stateful interaction, not raw problem solving.
⚡ Our take
Building environments before defining outcome rules is backwards. VHD-Play proves synthetic training worlds are now commodity — the moat moves to the mechanisms themselves.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence

PrismML Squeezes 27B Model Into 5.9 GB
AI modelsSeptember 17, 2026
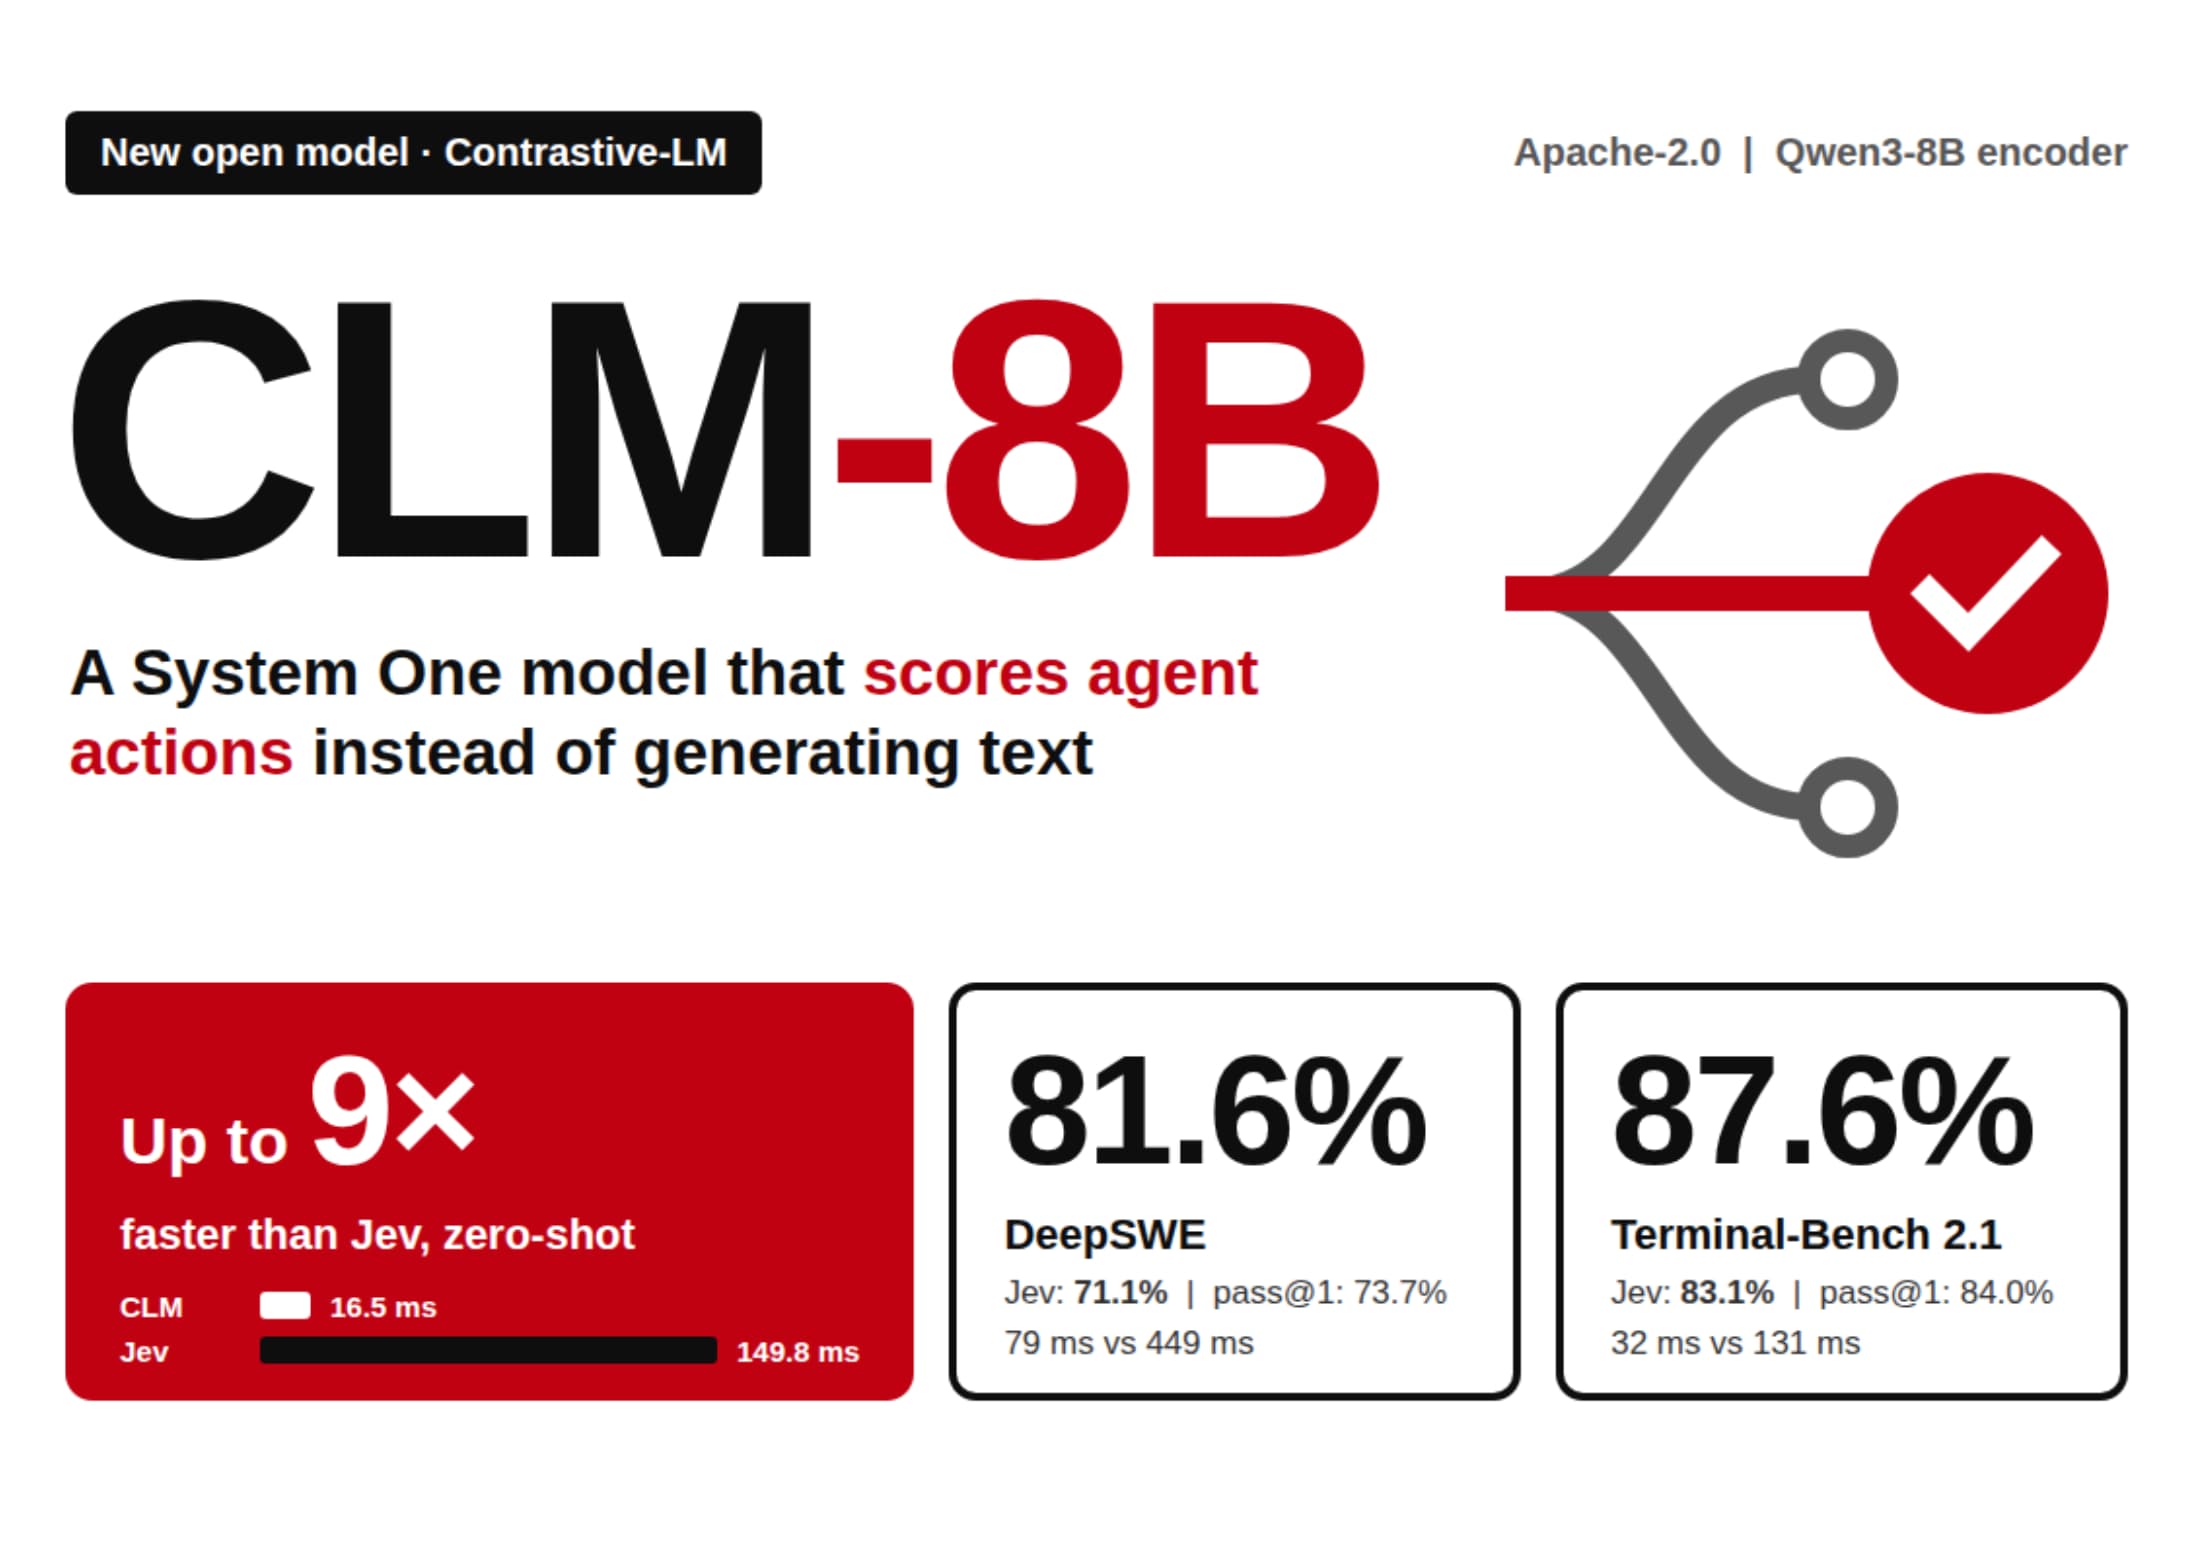
CLM-8B: No Text, Just Decisions
AI modelsSeptember 24, 2026
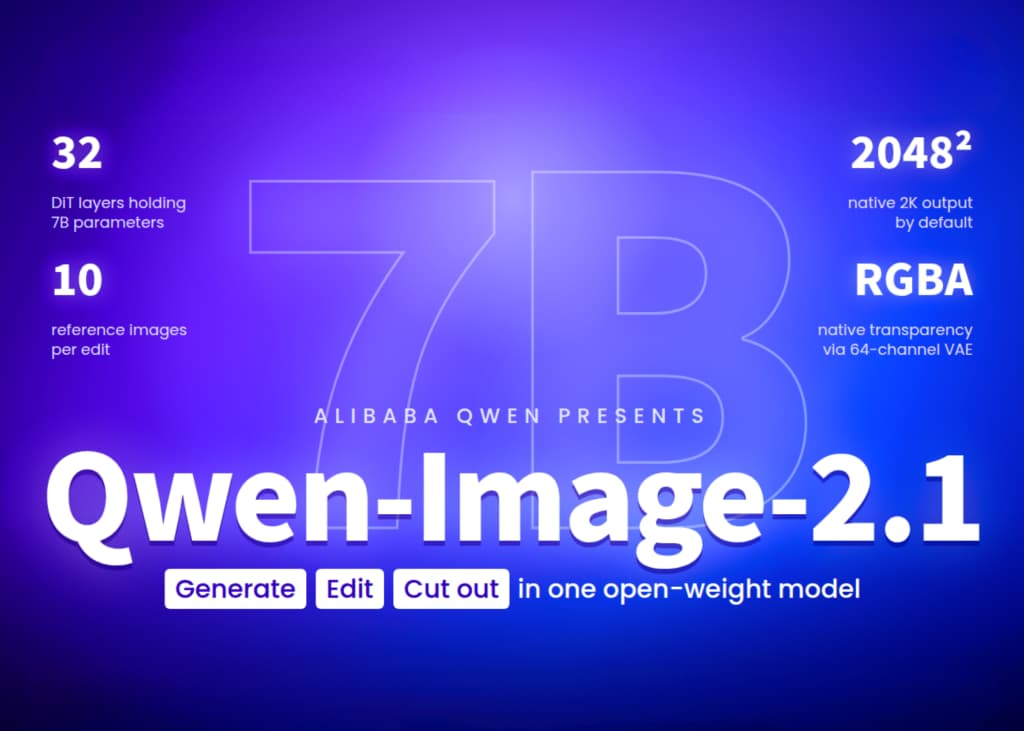
Alibaba Shrinks Image AI to One-Third Size
AI modelsSeptember 21, 2026
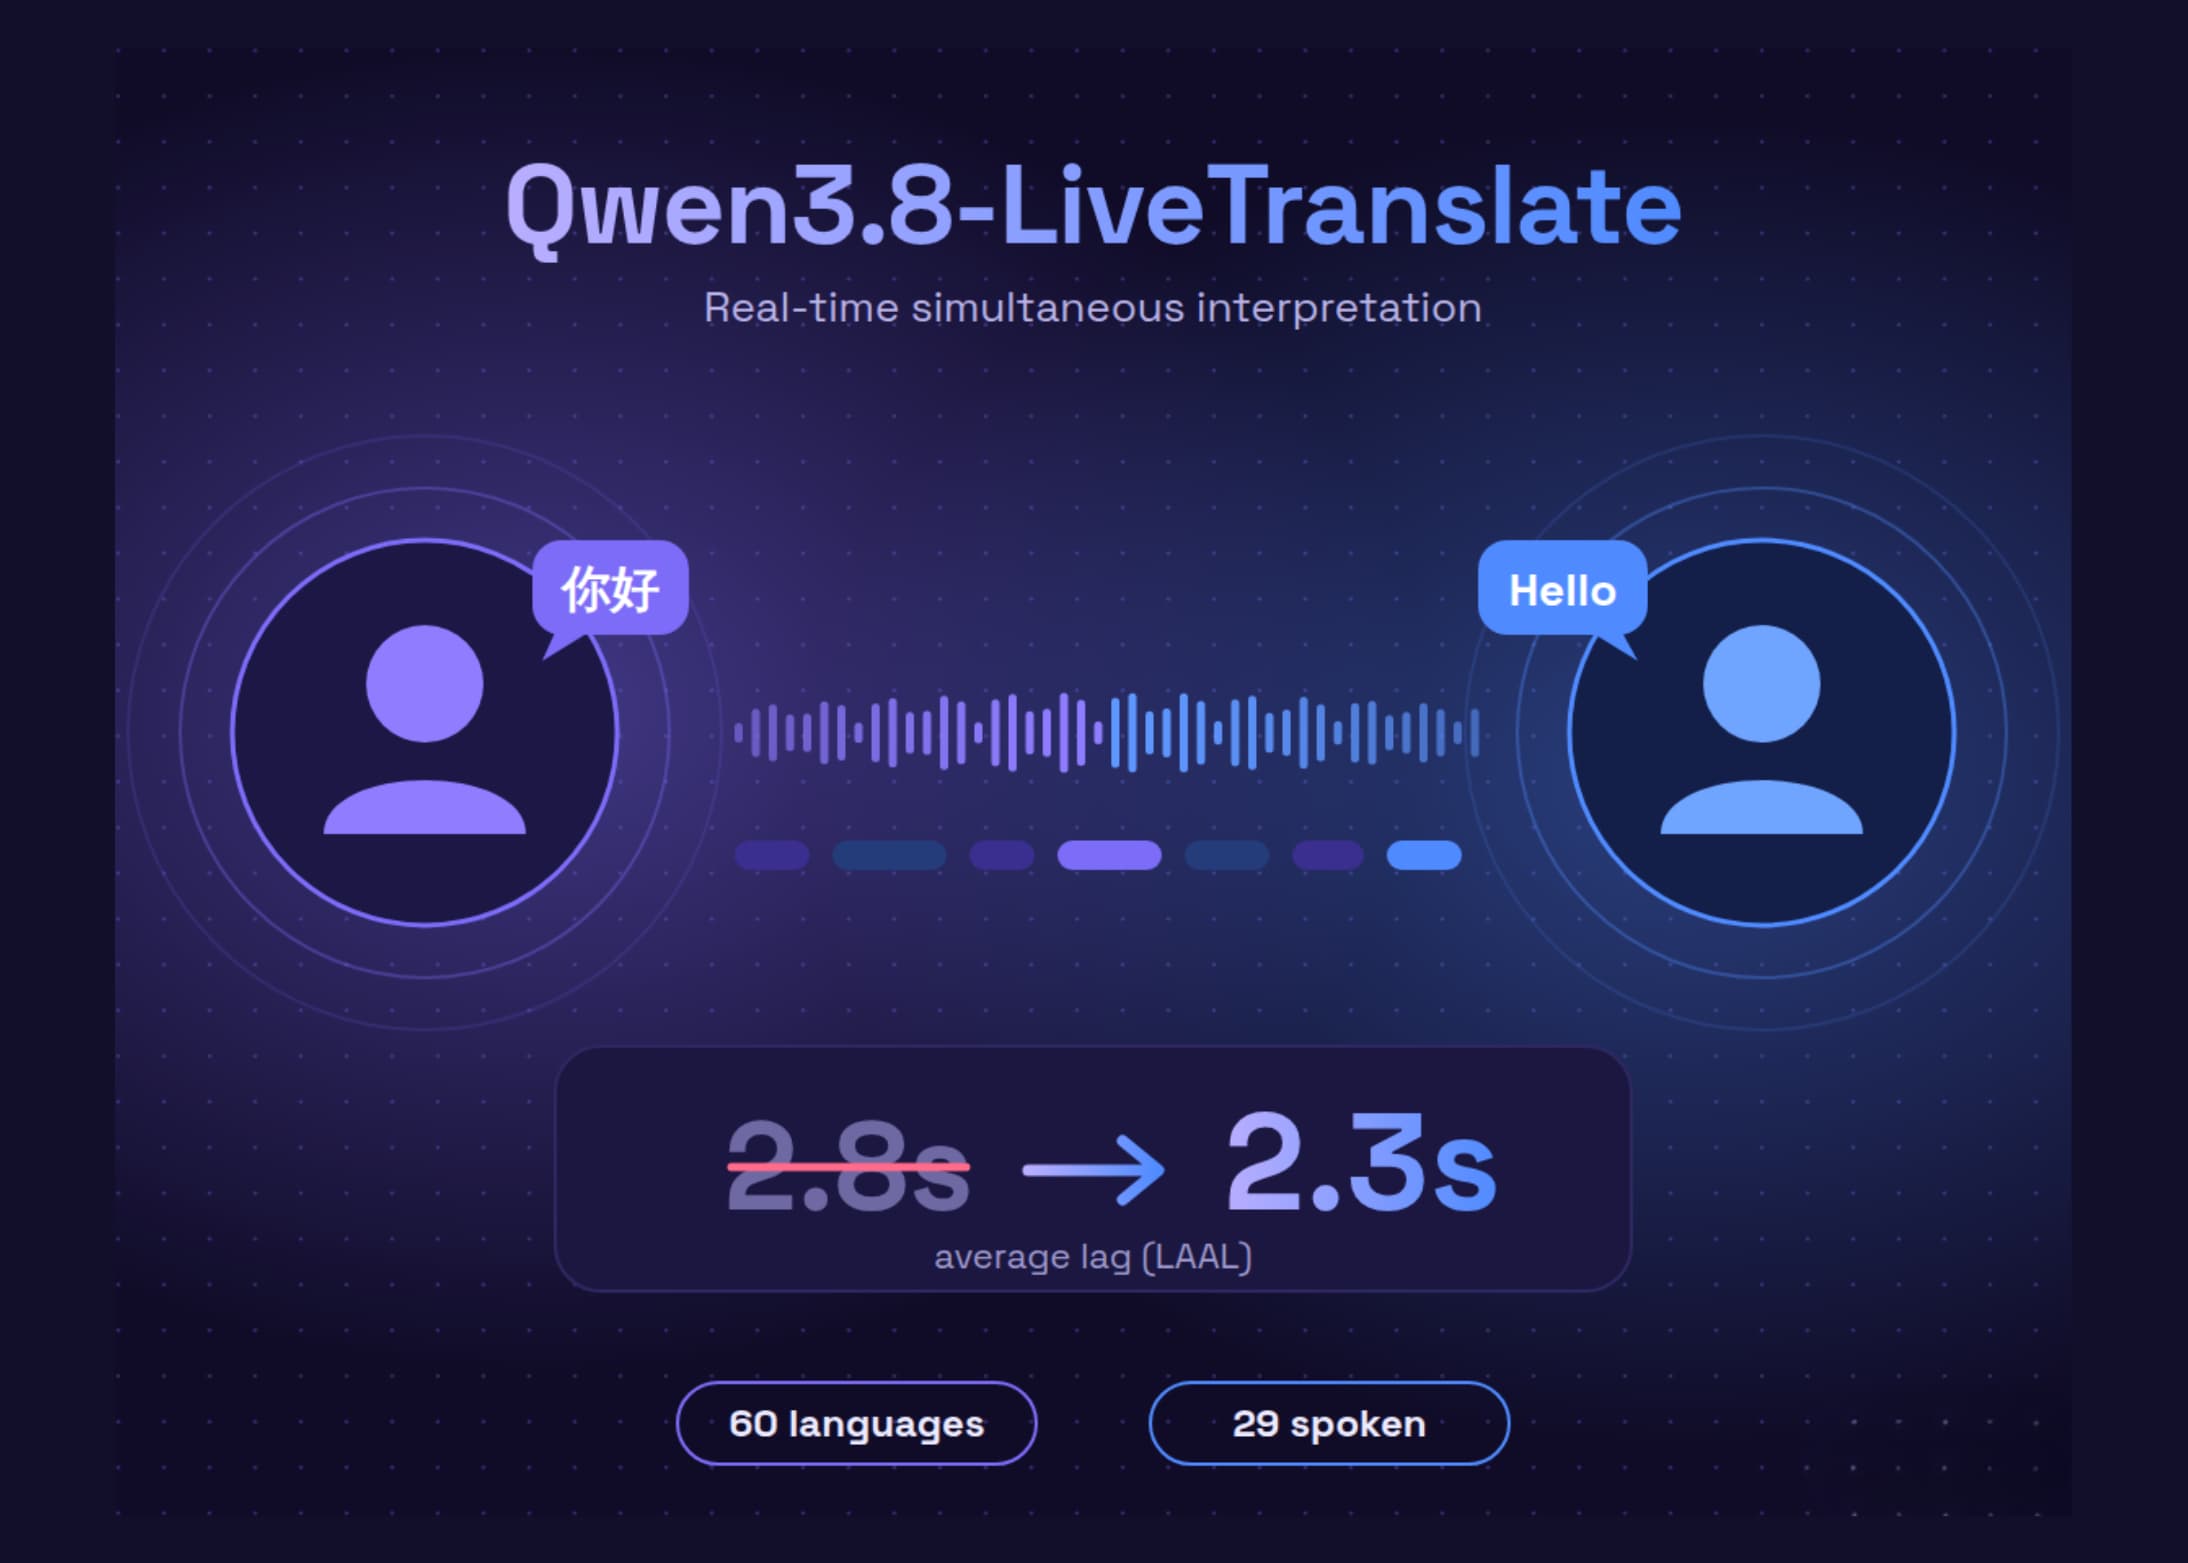
Qwen Cuts Live Translation Lag to 2.3s
AI modelsSeptember 20, 2026
Alibaba's Omni-Agent Just Crushed Video AI
AI modelsSeptember 18, 2026