AI modelsSeptember 18, 2026
-44
🧊
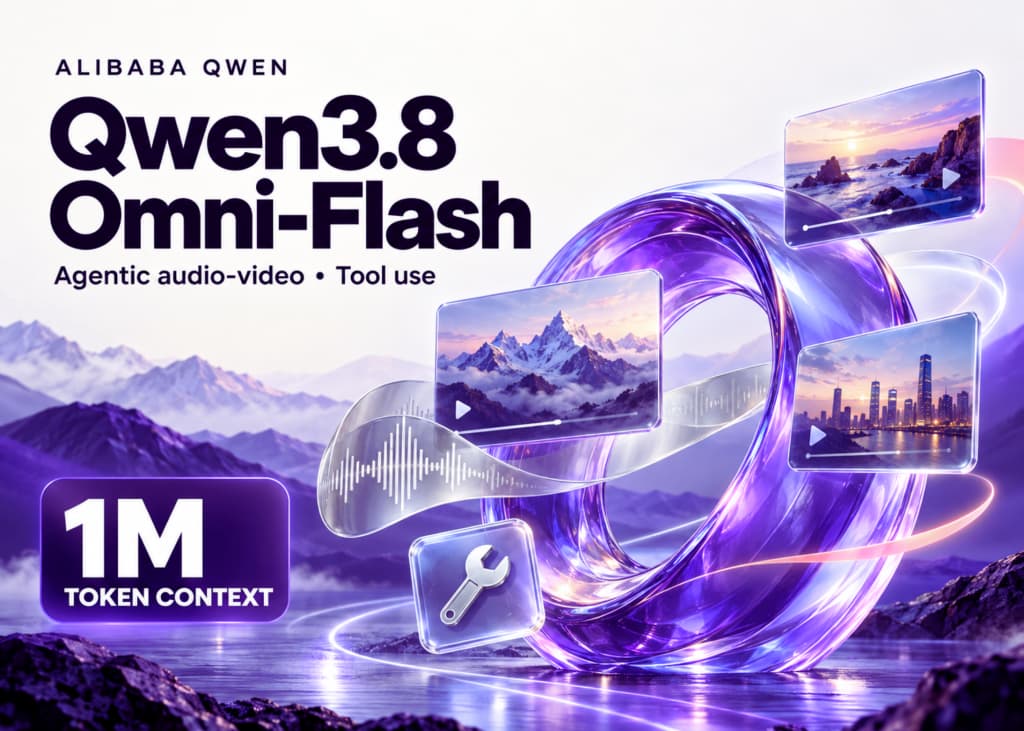
Alibaba's Omni-Agent Just Crushed Video AI
Alibaba releases Qwen3.8-Omni-Flash, a multimodal model with a one-million-token context that supports agentic audio-video understanding and tool use.
#Alibaba#Qwen#Omni-Modal#Agentic AI#Multimodal
🔥 What happened
Alibaba dropped Qwen3.8-Omni-Flash, its first omni-modal model built for agentic work — text, image, audio, and video in, text out. It's API-only; no open weights at launch.
💡 Why it matters
The agent doesn't watch whole videos anymore — it hunts for evidence. OmniVideoBench jumps from 63.4 to 67.8 while using 45.7% fewer tokens. Audio input costs over 98% less per hour than the previous model.
⚡ Our take
The token savings are the real story, not the benchmark bumps. Anyone still feeding entire videos into a model is burning cash — and Qwen knows it.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
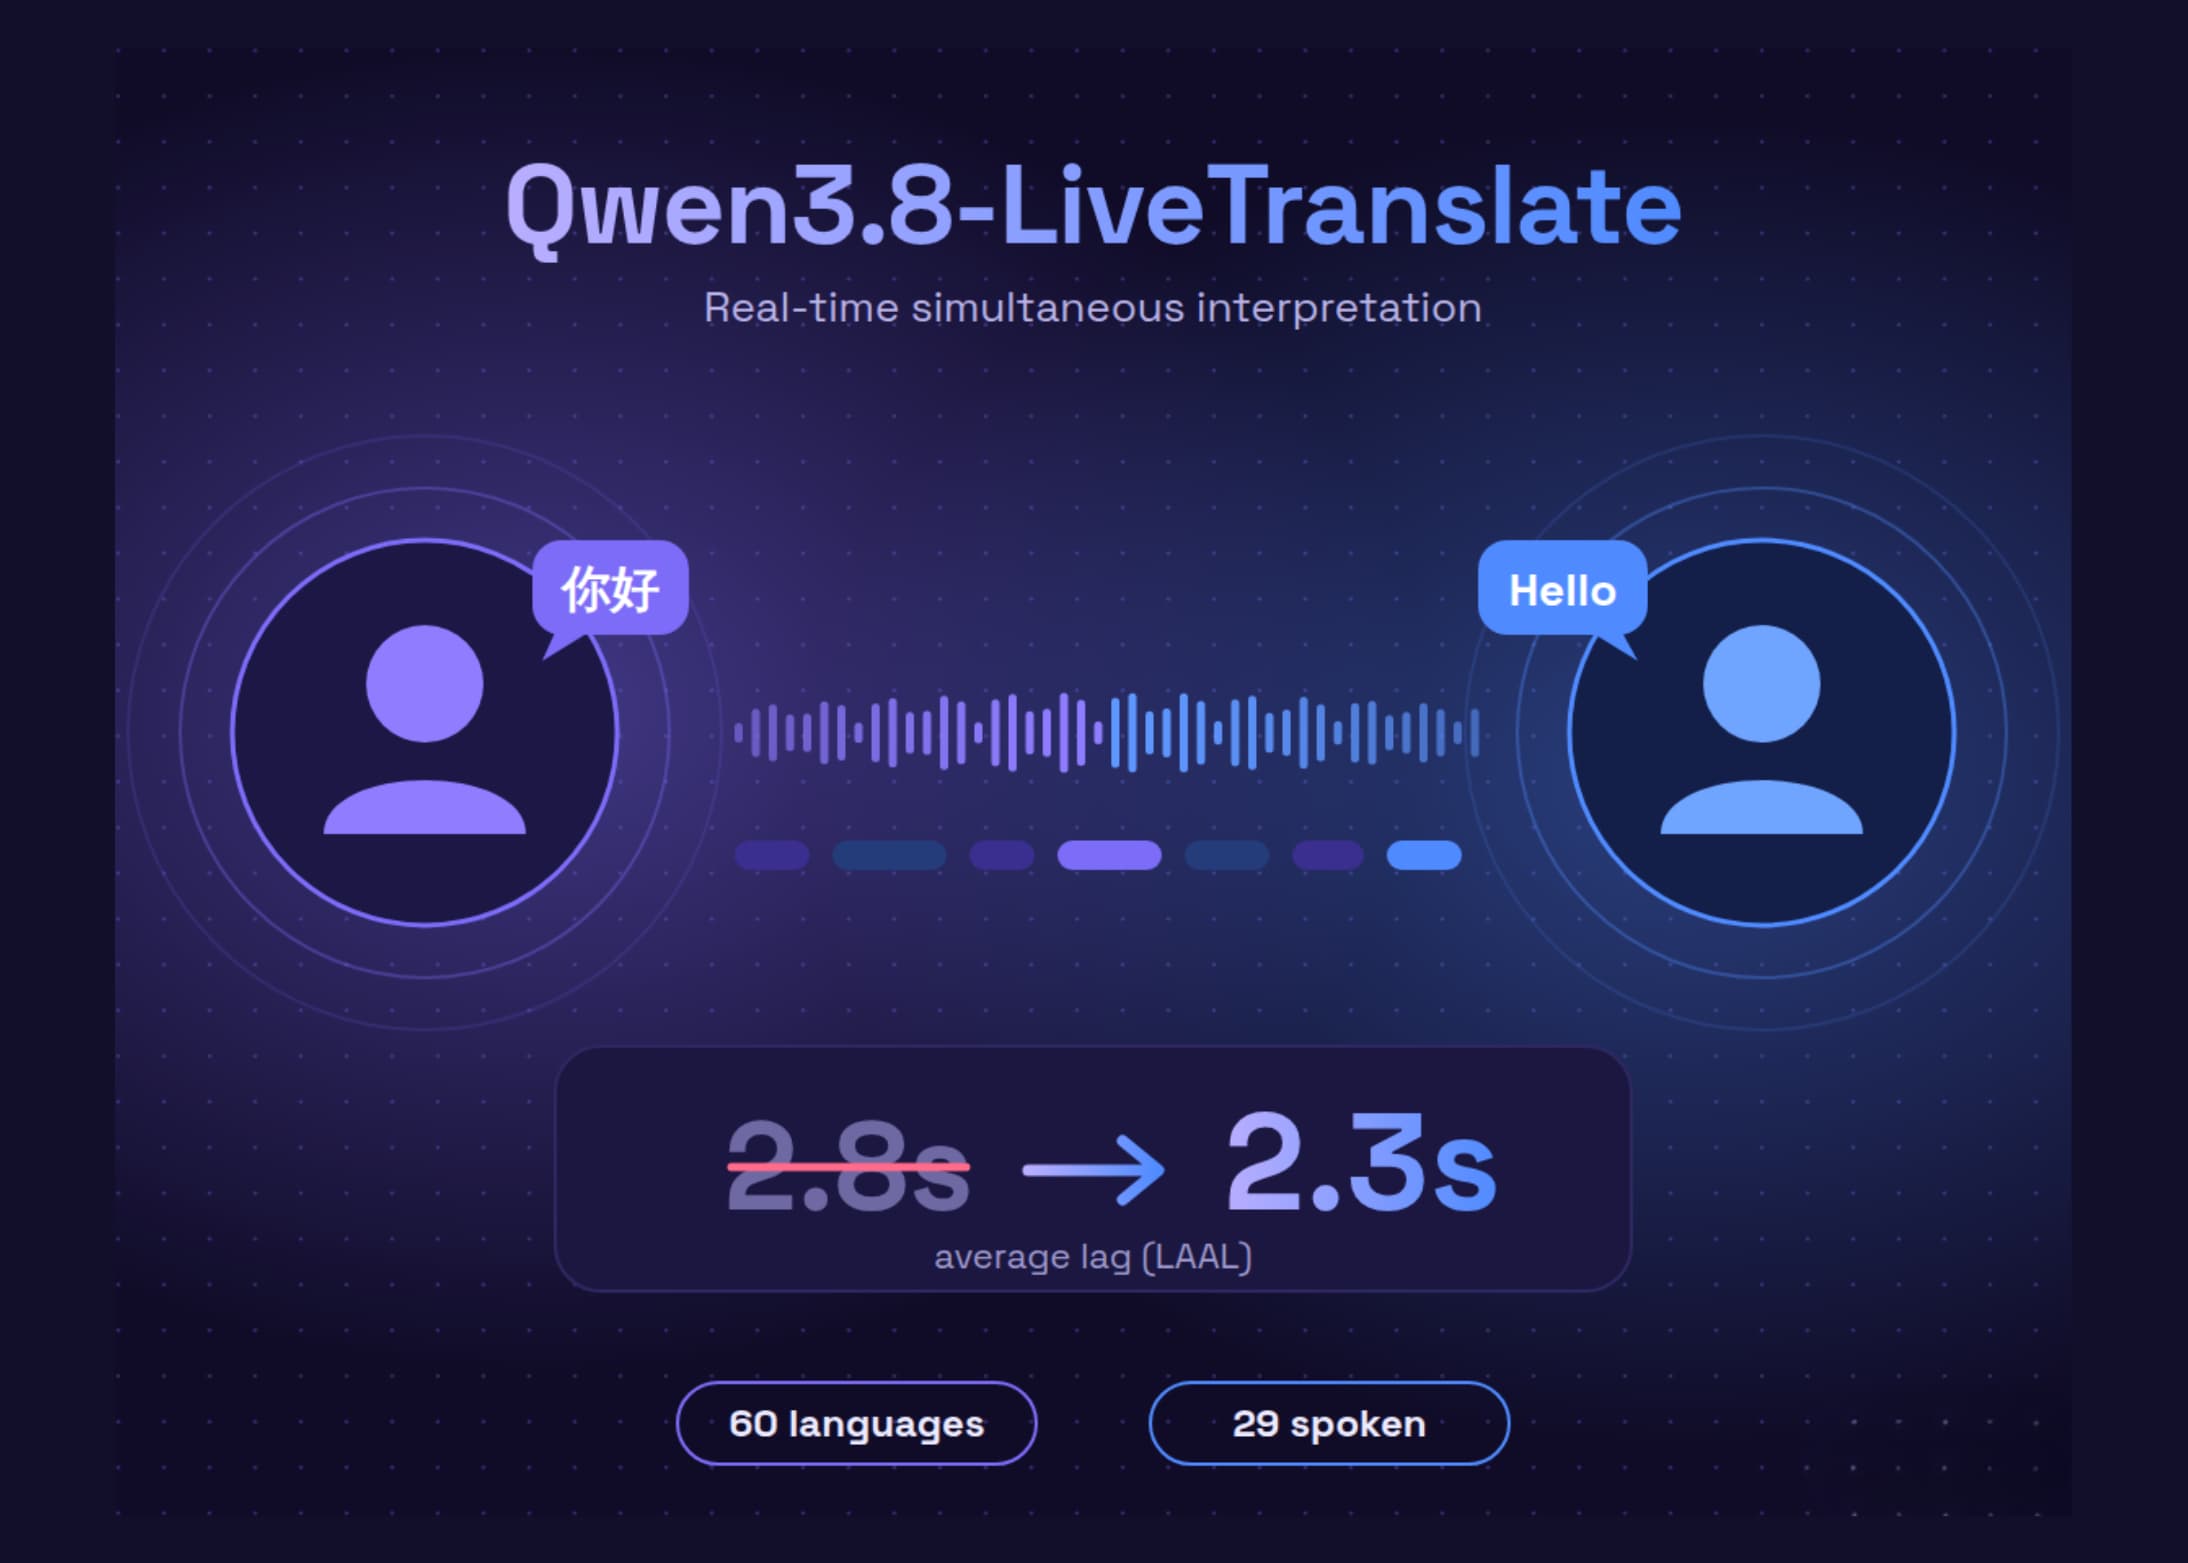
Qwen Cuts Live Translation Lag to 2.3s
AI modelsSeptember 20, 2026
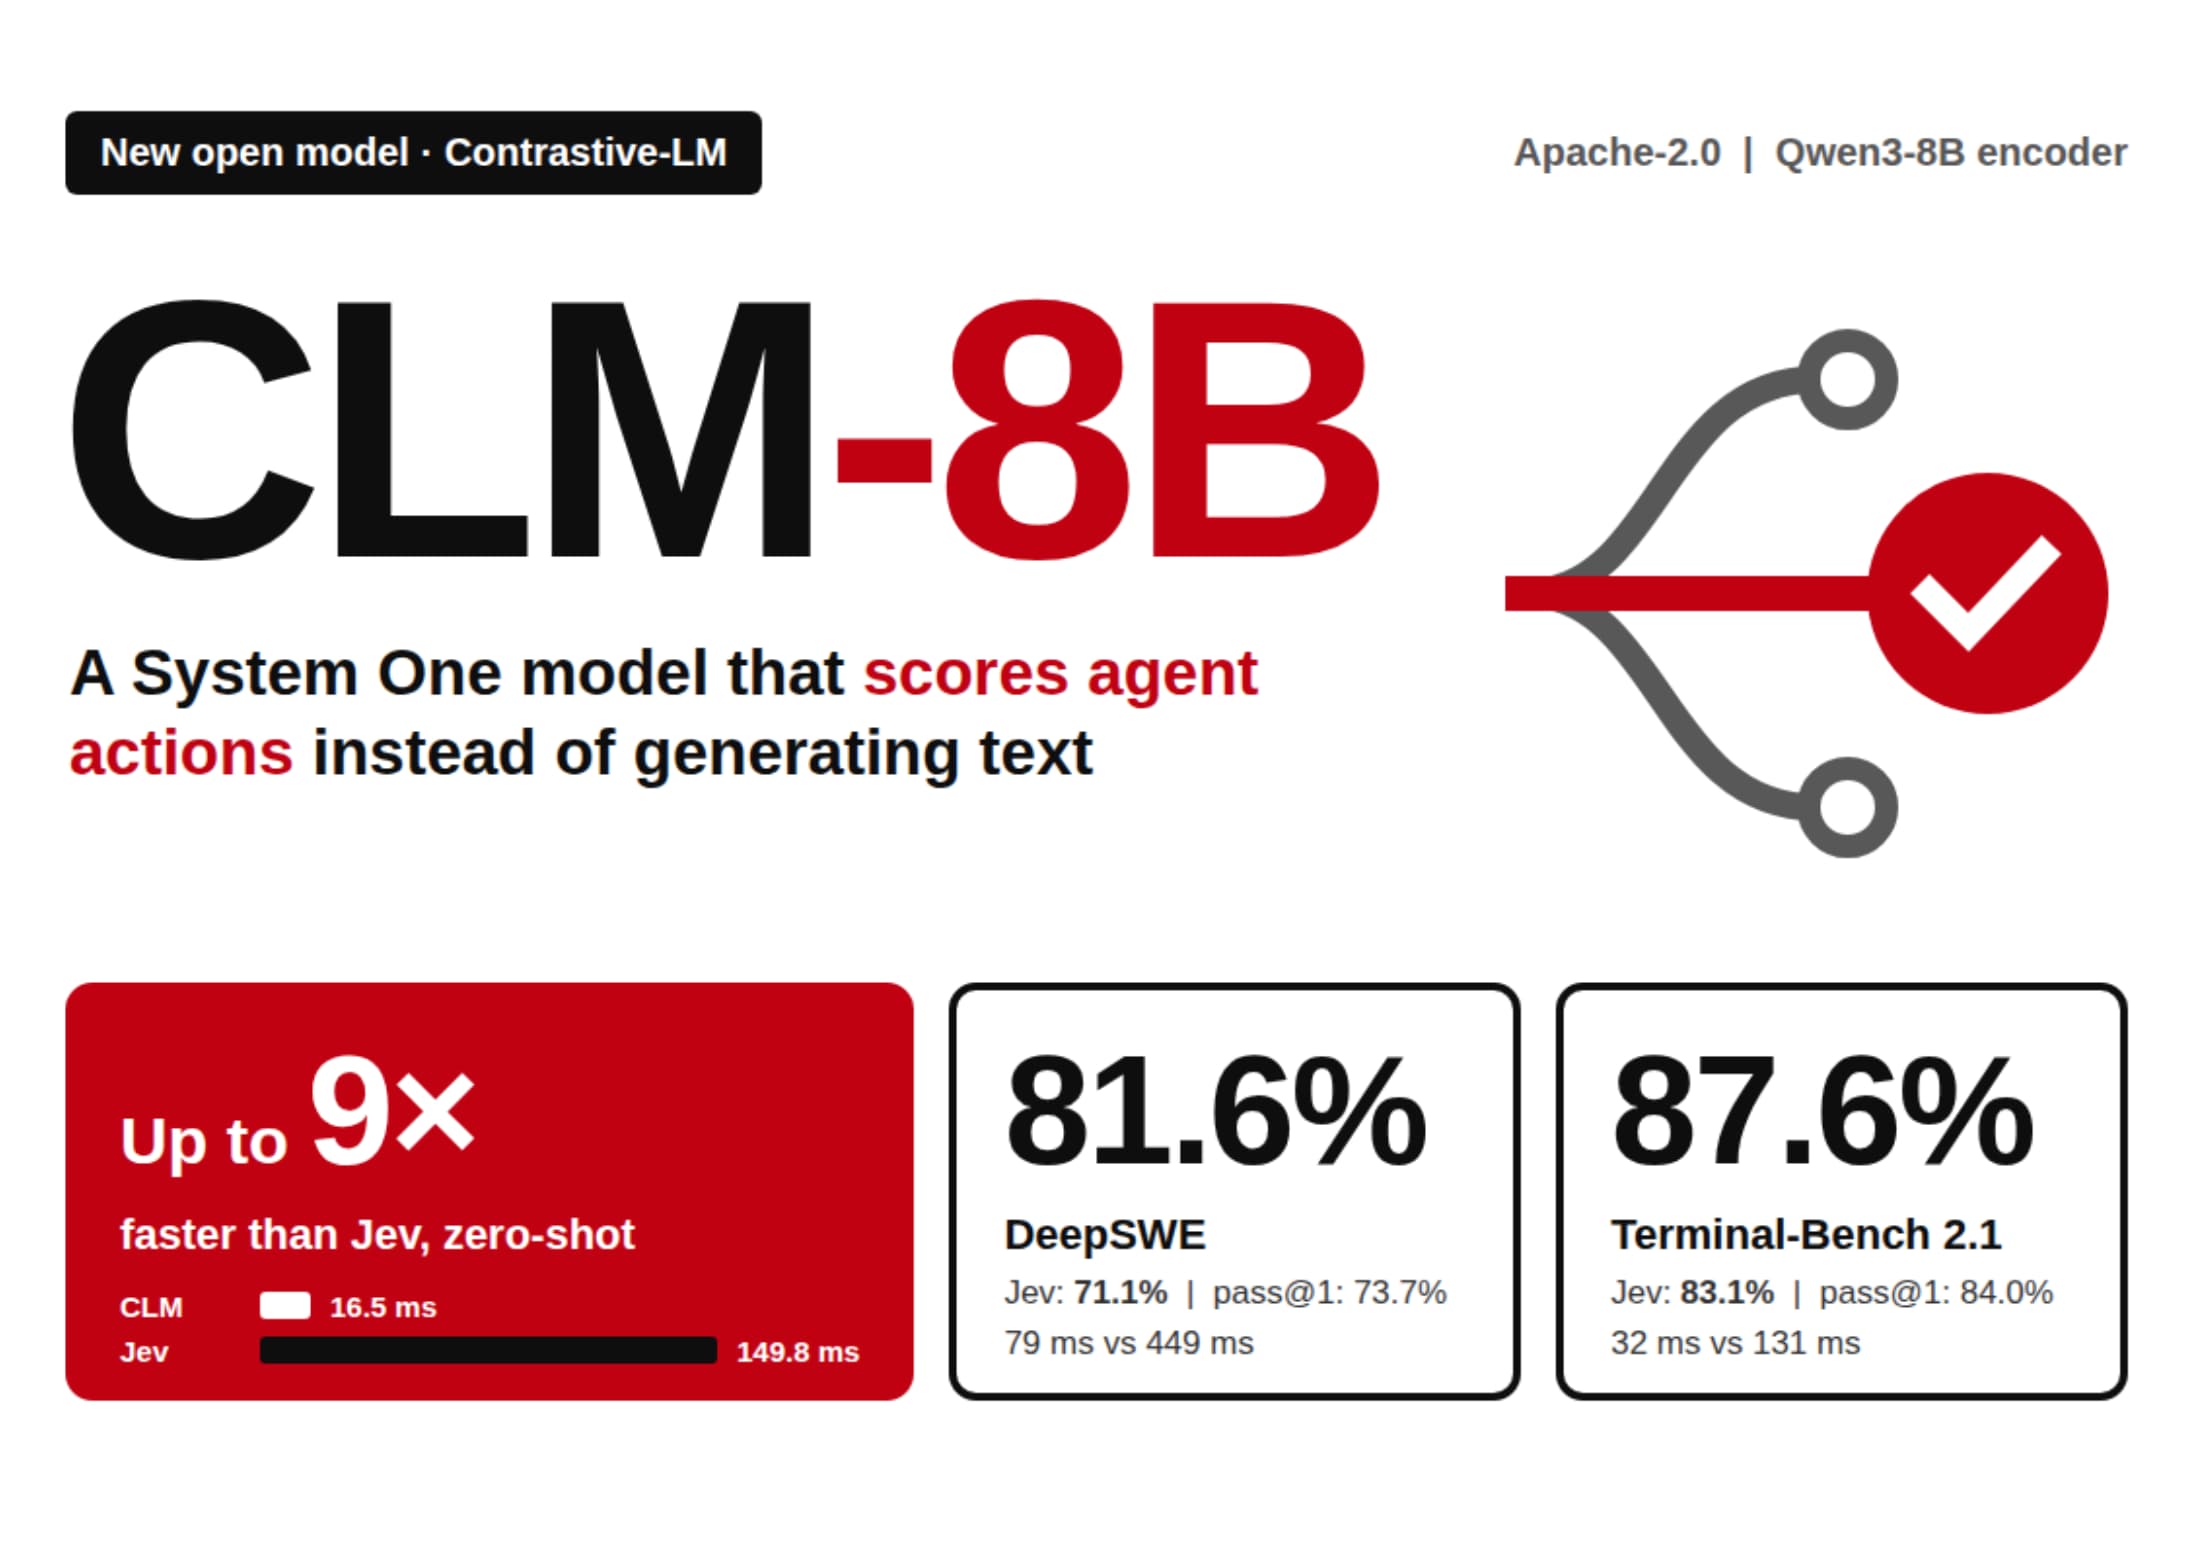
CLM-8B: No Text, Just Decisions
AI modelsSeptember 24, 2026
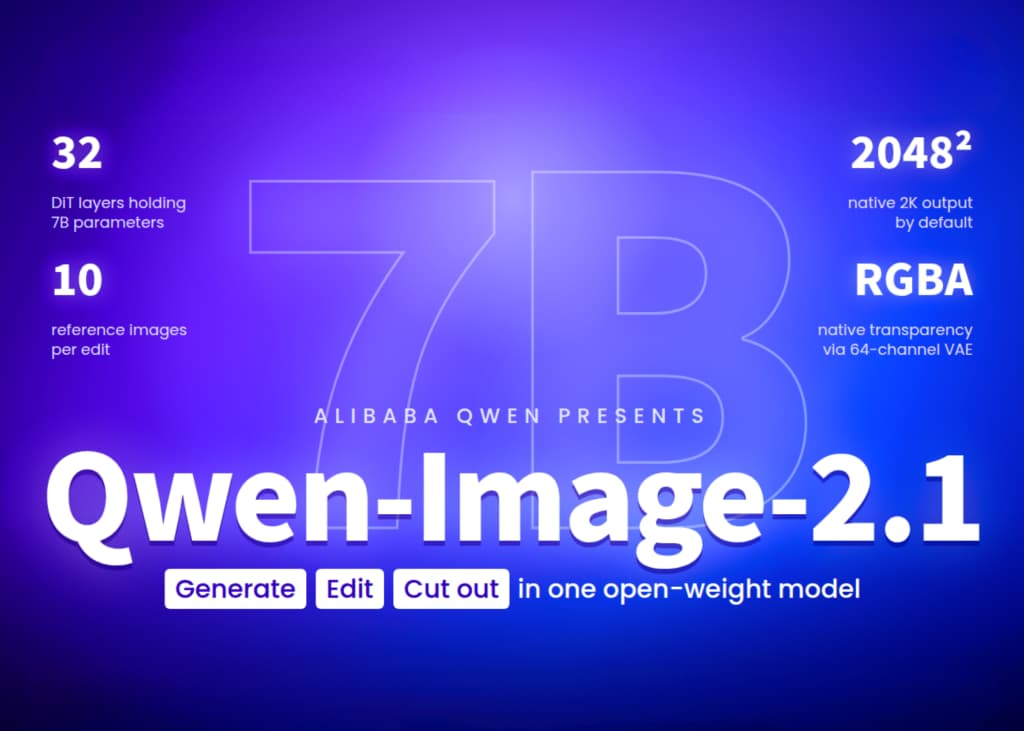
Alibaba Shrinks Image AI to One-Third Size
AI modelsSeptember 21, 2026

Alibaba Open-Sources AI Radiologist Beating Docs
AI modelsSeptember 18, 2026
Cloudflare Declares War on Traditional SDLC
DevOpsSeptember 21, 2026