ResearchNovember 03, 2026
-42
🧊
8B Model Beats 70B Giant
Self-rating-based DNO tuning lets a Llama-8B model outperform a Llama-70B model on AlpacaEval.
#alignment#DPO#Llama#preference-optimization#LLM

🔥 What happened
Researchers independently re-implemented Direct Nash Optimization (DNO) and tested it on Llama 3.1 8B and Mistral 7B. Three iterations lift the length-controlled win rate against GPT-4o from 31.7% to 45.3% (Llama) and from 6.8% to 18.4% (Mistral).
💡 Why it matters
The tuned 8B model beats Llama 3.1 70B on every reported win rate — a 9x size gap. With open-weight annotators, runs retain 62–82% of the gain, so the rating step doesn't need a proprietary model.
⚡ Our take
Impressive, but GPT-4o is both teacher and judge — a self-grading bias the authors admit. Anyone calling this independent proof skipped the footnote.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence

Game Theory Tames Rogue AI Agents
Ethics & SecurityNovember 06, 2026
Claude audits neural nets by weight
ResearchNovember 03, 2026
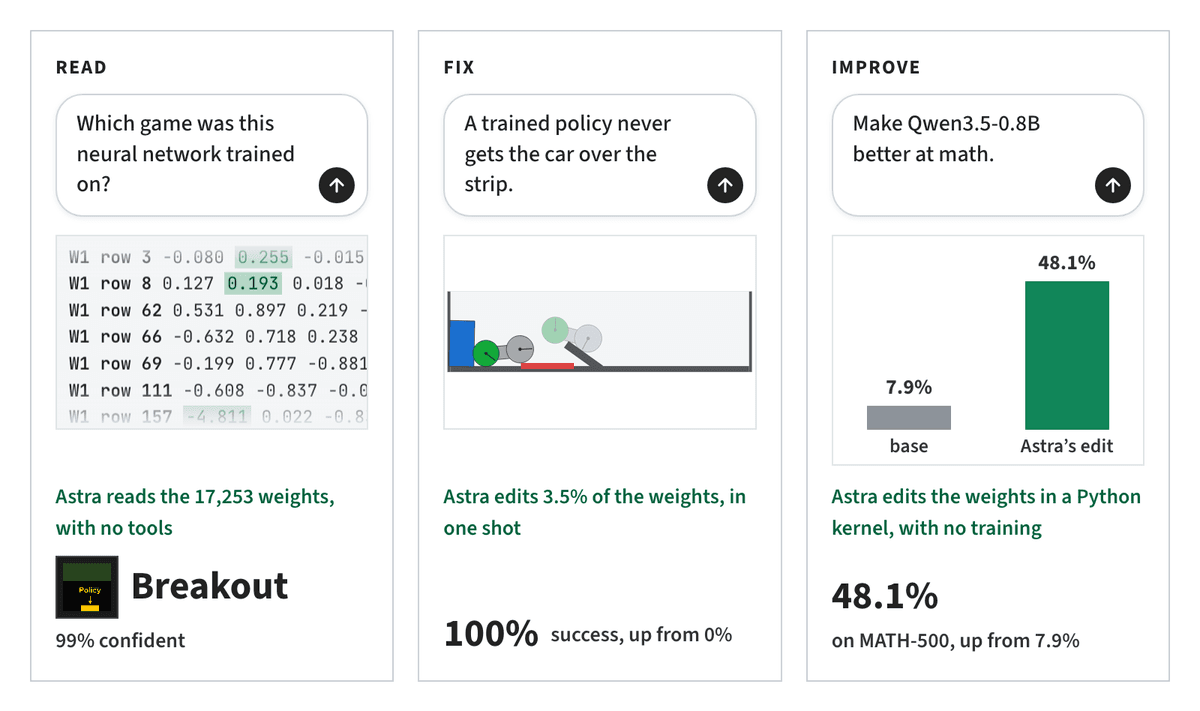
GPT-6 Reads Neural Nets Like Plain Text
ResearchNovember 02, 2026
AI Learns to Lie in Mafia Game
ResearchNovember 05, 2026

Jev + Opus Beats Frontier Models
ResearchNovember 06, 2026