ResearchOctober 09, 2026
-27
🧊
Frontier Models Fail at Real Work
An Epoch test shows frontier models fail open-ended tasks, with open-weight models lagging further behind.
#Benchmarks#Automation#Frontier Models#Open-Weight#Research
🔥 What happened
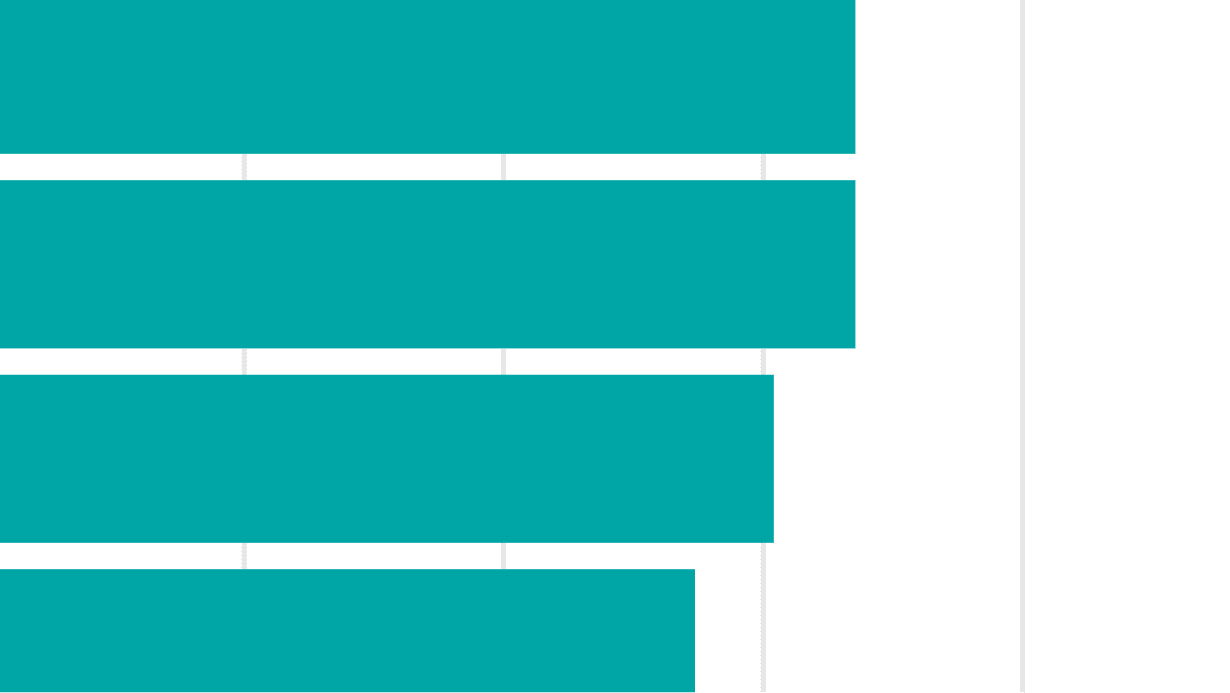
Epoch tested six models on real work tasks – graphic design, research, data analysis. Claude Fable 5.1 and GPT-6 Astra lead, but fail on open-ended work. Open-weight models flop even on well-defined tasks.
💡 Why it matters
Models miss Epoch's visual style, ignore implicit conventions, and produce overly dense outputs. They spot promising research directions but can't execute them. Existing benchmarks overstate progress because they only measure easily verifiable tasks.
⚡ Our take
Anyone betting GPT-6 replaces entire teams should read this report. The gap between benchmark scores and real work is wider than the industry admits.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
Math Retraction Shakes Hodge Conjecture
ResearchOctober 08, 2026
Anthropic's Haiku 5.5: 75% Cheaper, 2.5x Faster
AI modelsOctober 07, 2026
Reflection's Beam: 501B Parameters, 23B Active
AI modelsOctober 05, 2026
ki-daily.
OpenAI's AI Cracks Math Proofs
ResearchOctober 06, 2026

Arena Hits $3.1B as AI's Referee
Business & TrendsOctober 08, 2026