Tools & ProjectsOctober 03, 2026
10
🌱
Prime Intellect's Inference Power Play
Prime Intellect launches Prime Inference for frontier open models on Blackwell hardware.
#Prime Intellect#Inference#Open Models#NVIDIA Blackwell#Serverless
🔥 What happened
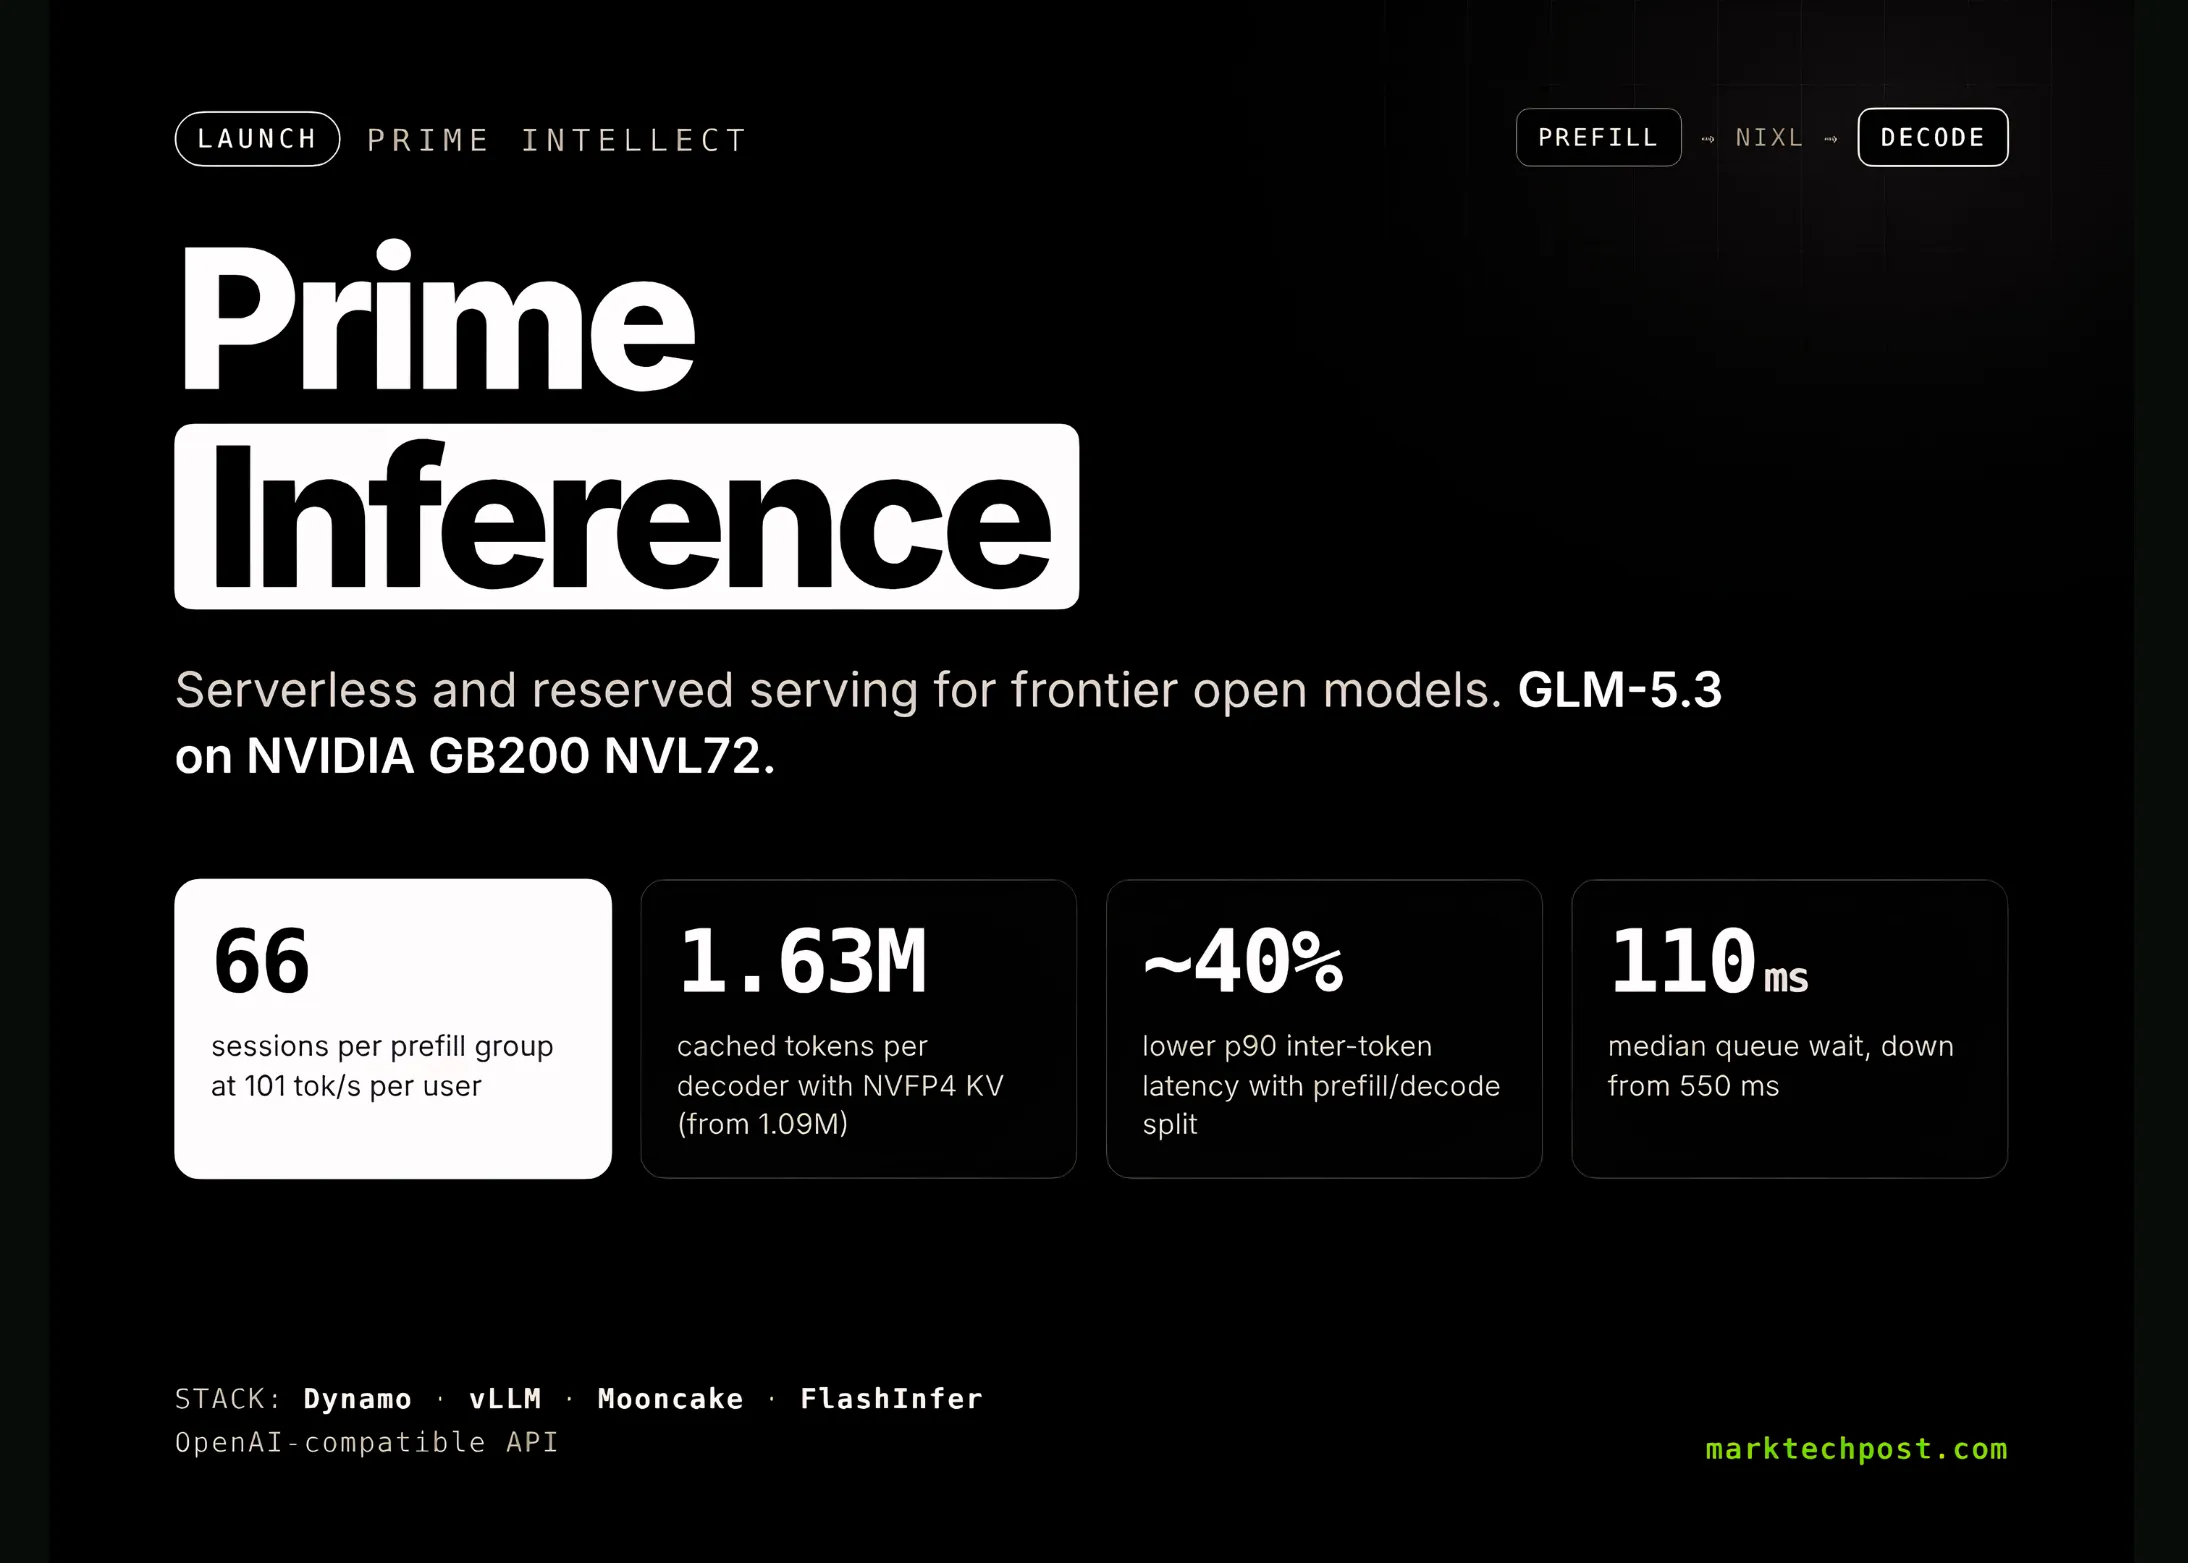
Prime Intellect launched Prime Inference, a serving platform for frontier open-source models. Before going public, it processed nearly a trillion tokens daily internally – from RL rollouts, synthetic data, and coding agents.
💡 Why it matters
The stack (Dynamo, vLLM, Mooncake, FlashInfer) hits 101 tokens/s per user across 66 sessions per prefill group. NVFP4 KV compression boosts cache capacity from 1.09M to 1.63M tokens per decoder – a massive leap for agentic workloads.
⚡ Our take
Prime Intellect isn't just building models; it's building the infrastructure that powers them. Owning both training and serving could reshape the open-source inference market.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.