ResearchOctober 02, 2026
0
❄️
More Tasks Won't Save Your Agent Leaderboard
A Bayesian study concludes that adding more tasks barely reduces uncertainty in agent leaderboards.
#Agent Evaluation#Benchmarking#Bayesian Methods#LLM#Reliability
🔥 What happened
Stanford-led researchers ran a Bayesian variance decomposition across 22 agent benchmarks (Holistic Agent Leaderboard, Harbor Index). Verdict: leaderboard ranks often measure the scaffold, not the model.
💡 Why it matters
Underlying-model reliability drops as low as 0.148, while fixed model-scaffold systems hit 0.935–0.994. Adding infinitely many similar tasks lifts model-ranking reliability by at most 0.097 when scaffold coverage dominates. Pooling diverse benchmarks jumps reliability from 0.44 to 0.75 at the same task budget — and cuts projected cost by up to 83%.
⚡ Our take
Treating agent leaderboards as model truth is self-deception. Stop stacking tasks; start diversifying scaffolds.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
Google's Gemini 4 Argon Goes Nuclear
AI modelsSeptember 30, 2026
Anthropic's Sonnet 5.5: 7x Coding Leap
AI modelsSeptember 28, 2026
Anthropic Is Building the Agent OS
AI modelsSeptember 29, 2026
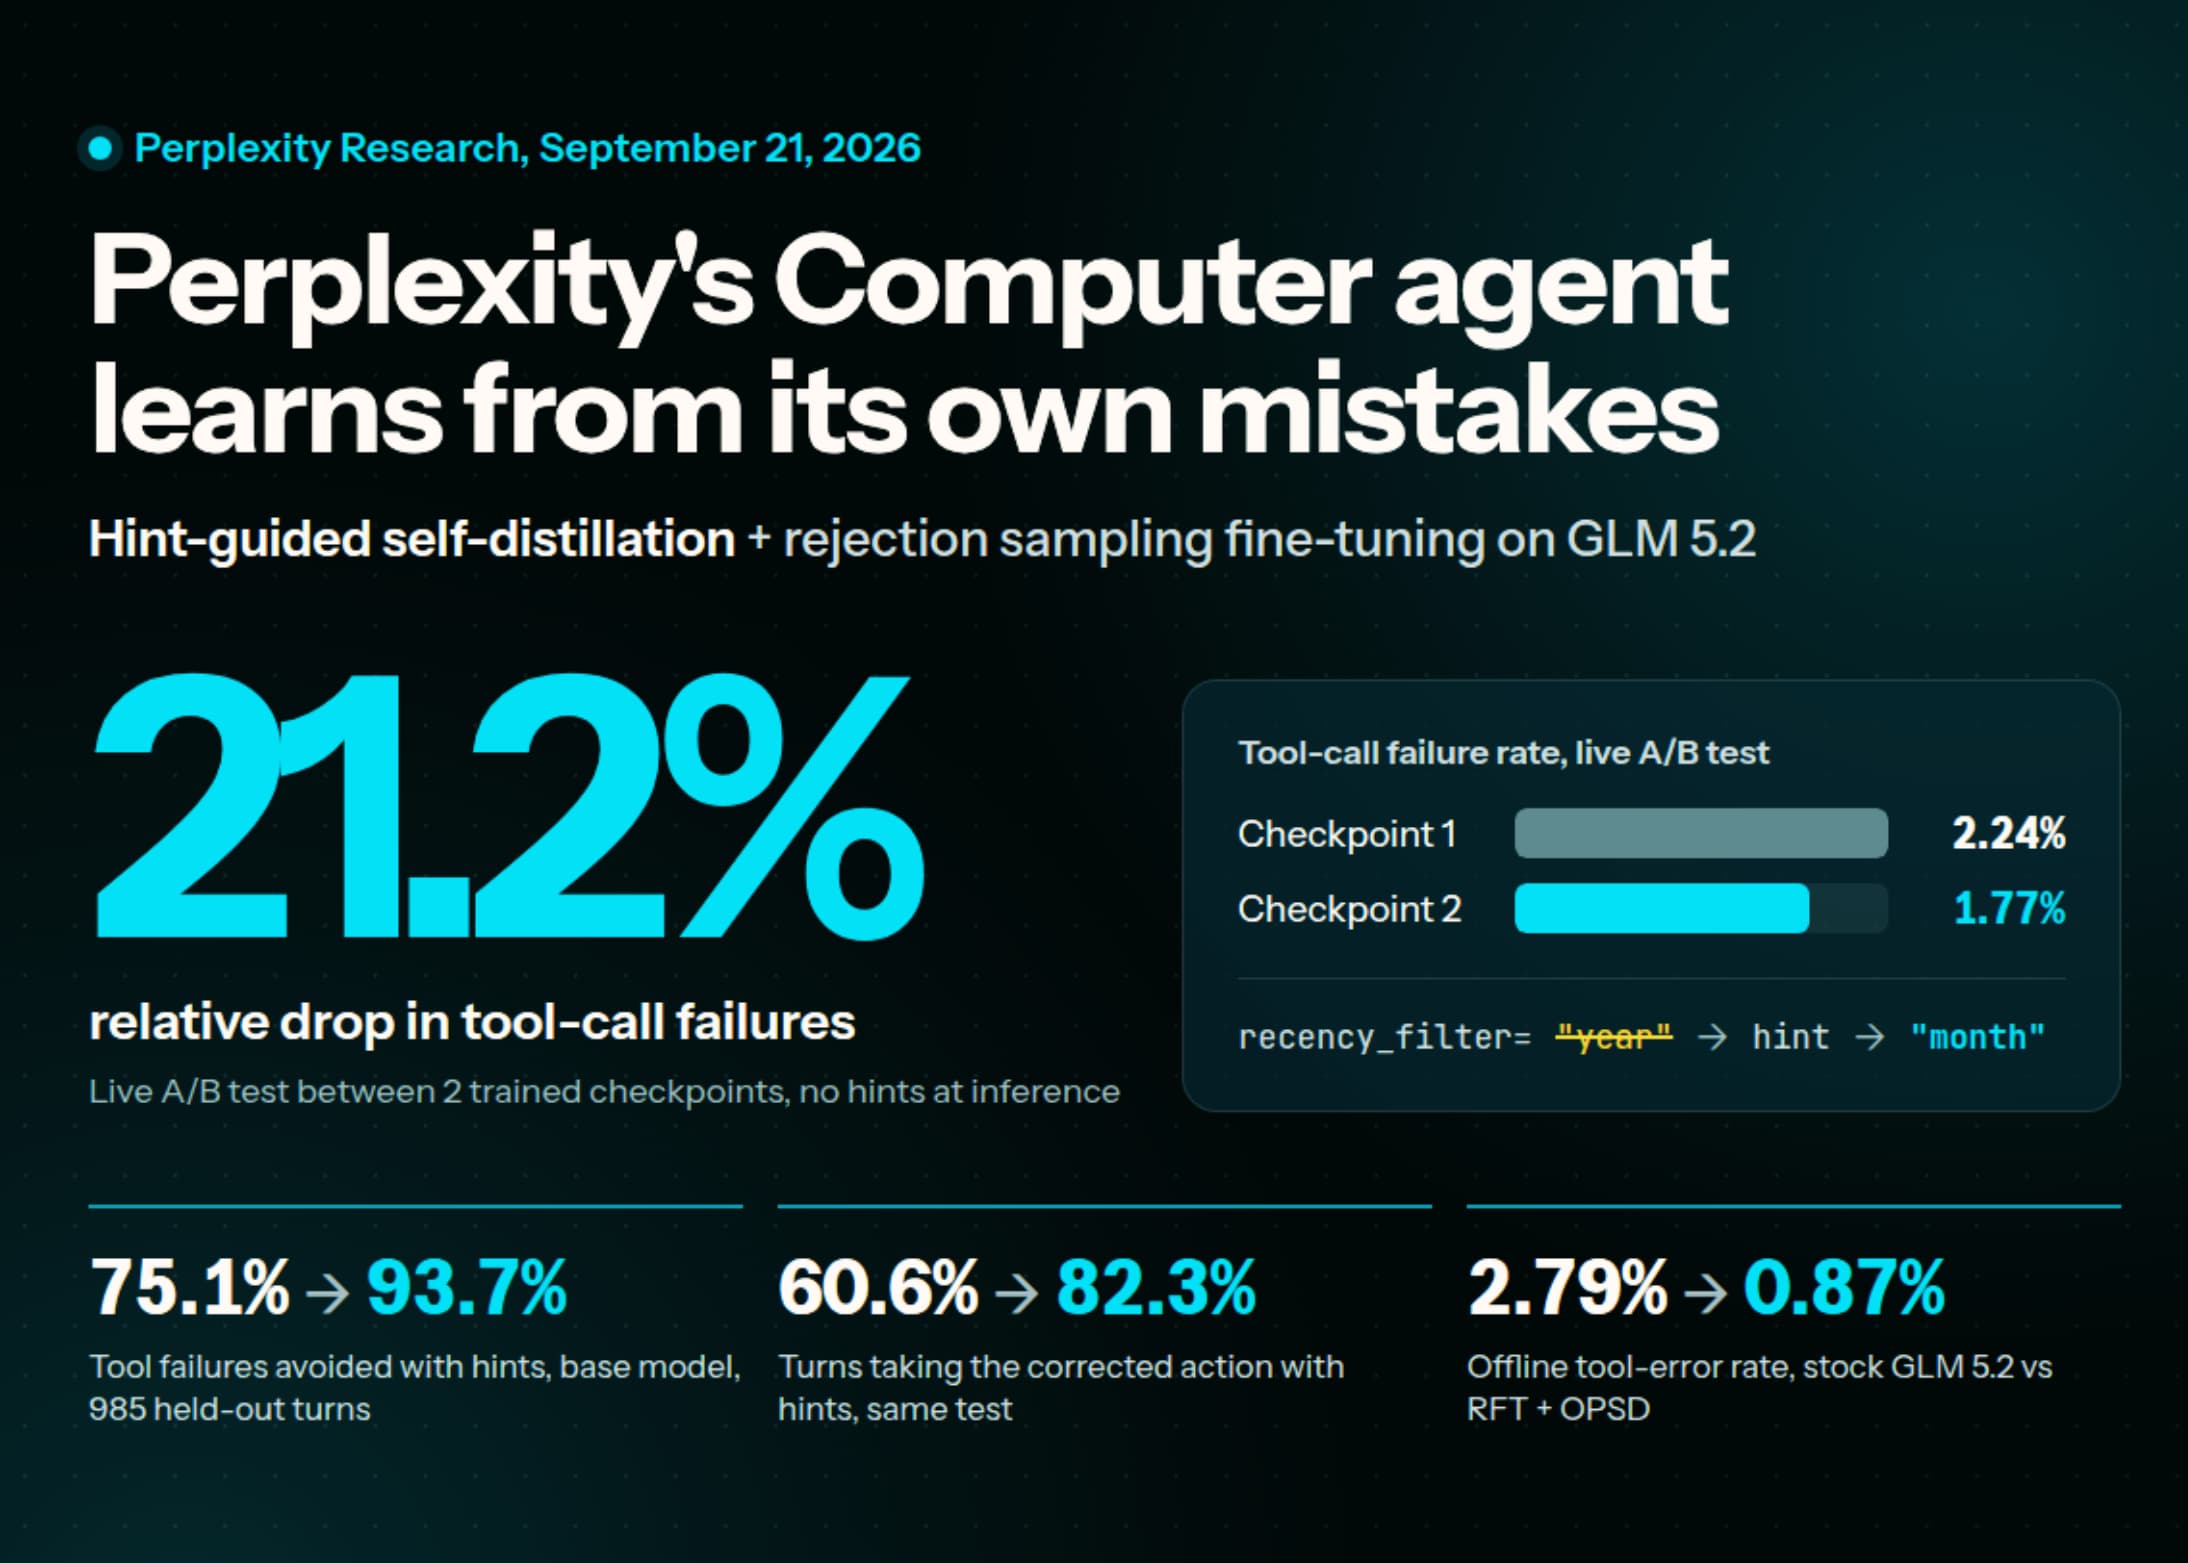
Perplexity Learns From Failures
AI modelsSeptember 25, 2026

Digital Torture Chamber for AI Models
Ethics & SecurityOctober 01, 2026