AI modelsSeptember 28, 2026
4
🌱
Jeff: Tiny Models Beat Jev
Jeff: 0.8B decision models run locally at ~30 ms per call.
#LLM#Qwen#Gemma#Local Inference#Classification
🔥 What happened
Jeff, an independent project, dropped tiny fine-tunes of Qwen3.5 and Gemma 4 (0.8B and 2B) for zero-shot classification. They return calibrated probabilities in a single forward pass — 22 ms on an RTX PRO 6000, 28 ms on an M4 Max.
💡 Why it matters
Jeff beats the much larger Jev on 5 of 6 classification benchmarks (79.1 vs. 83.0 overall) and hits 95.8% accuracy after a 30-minute fine-tune. No cloud GPUs, no closed-model outputs in training.
⚡ Our take
If you're still calling GPT-4o for intent detection, you're burning money and latency. Jeff proves 0.8B parameters are enough — if you train them right.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
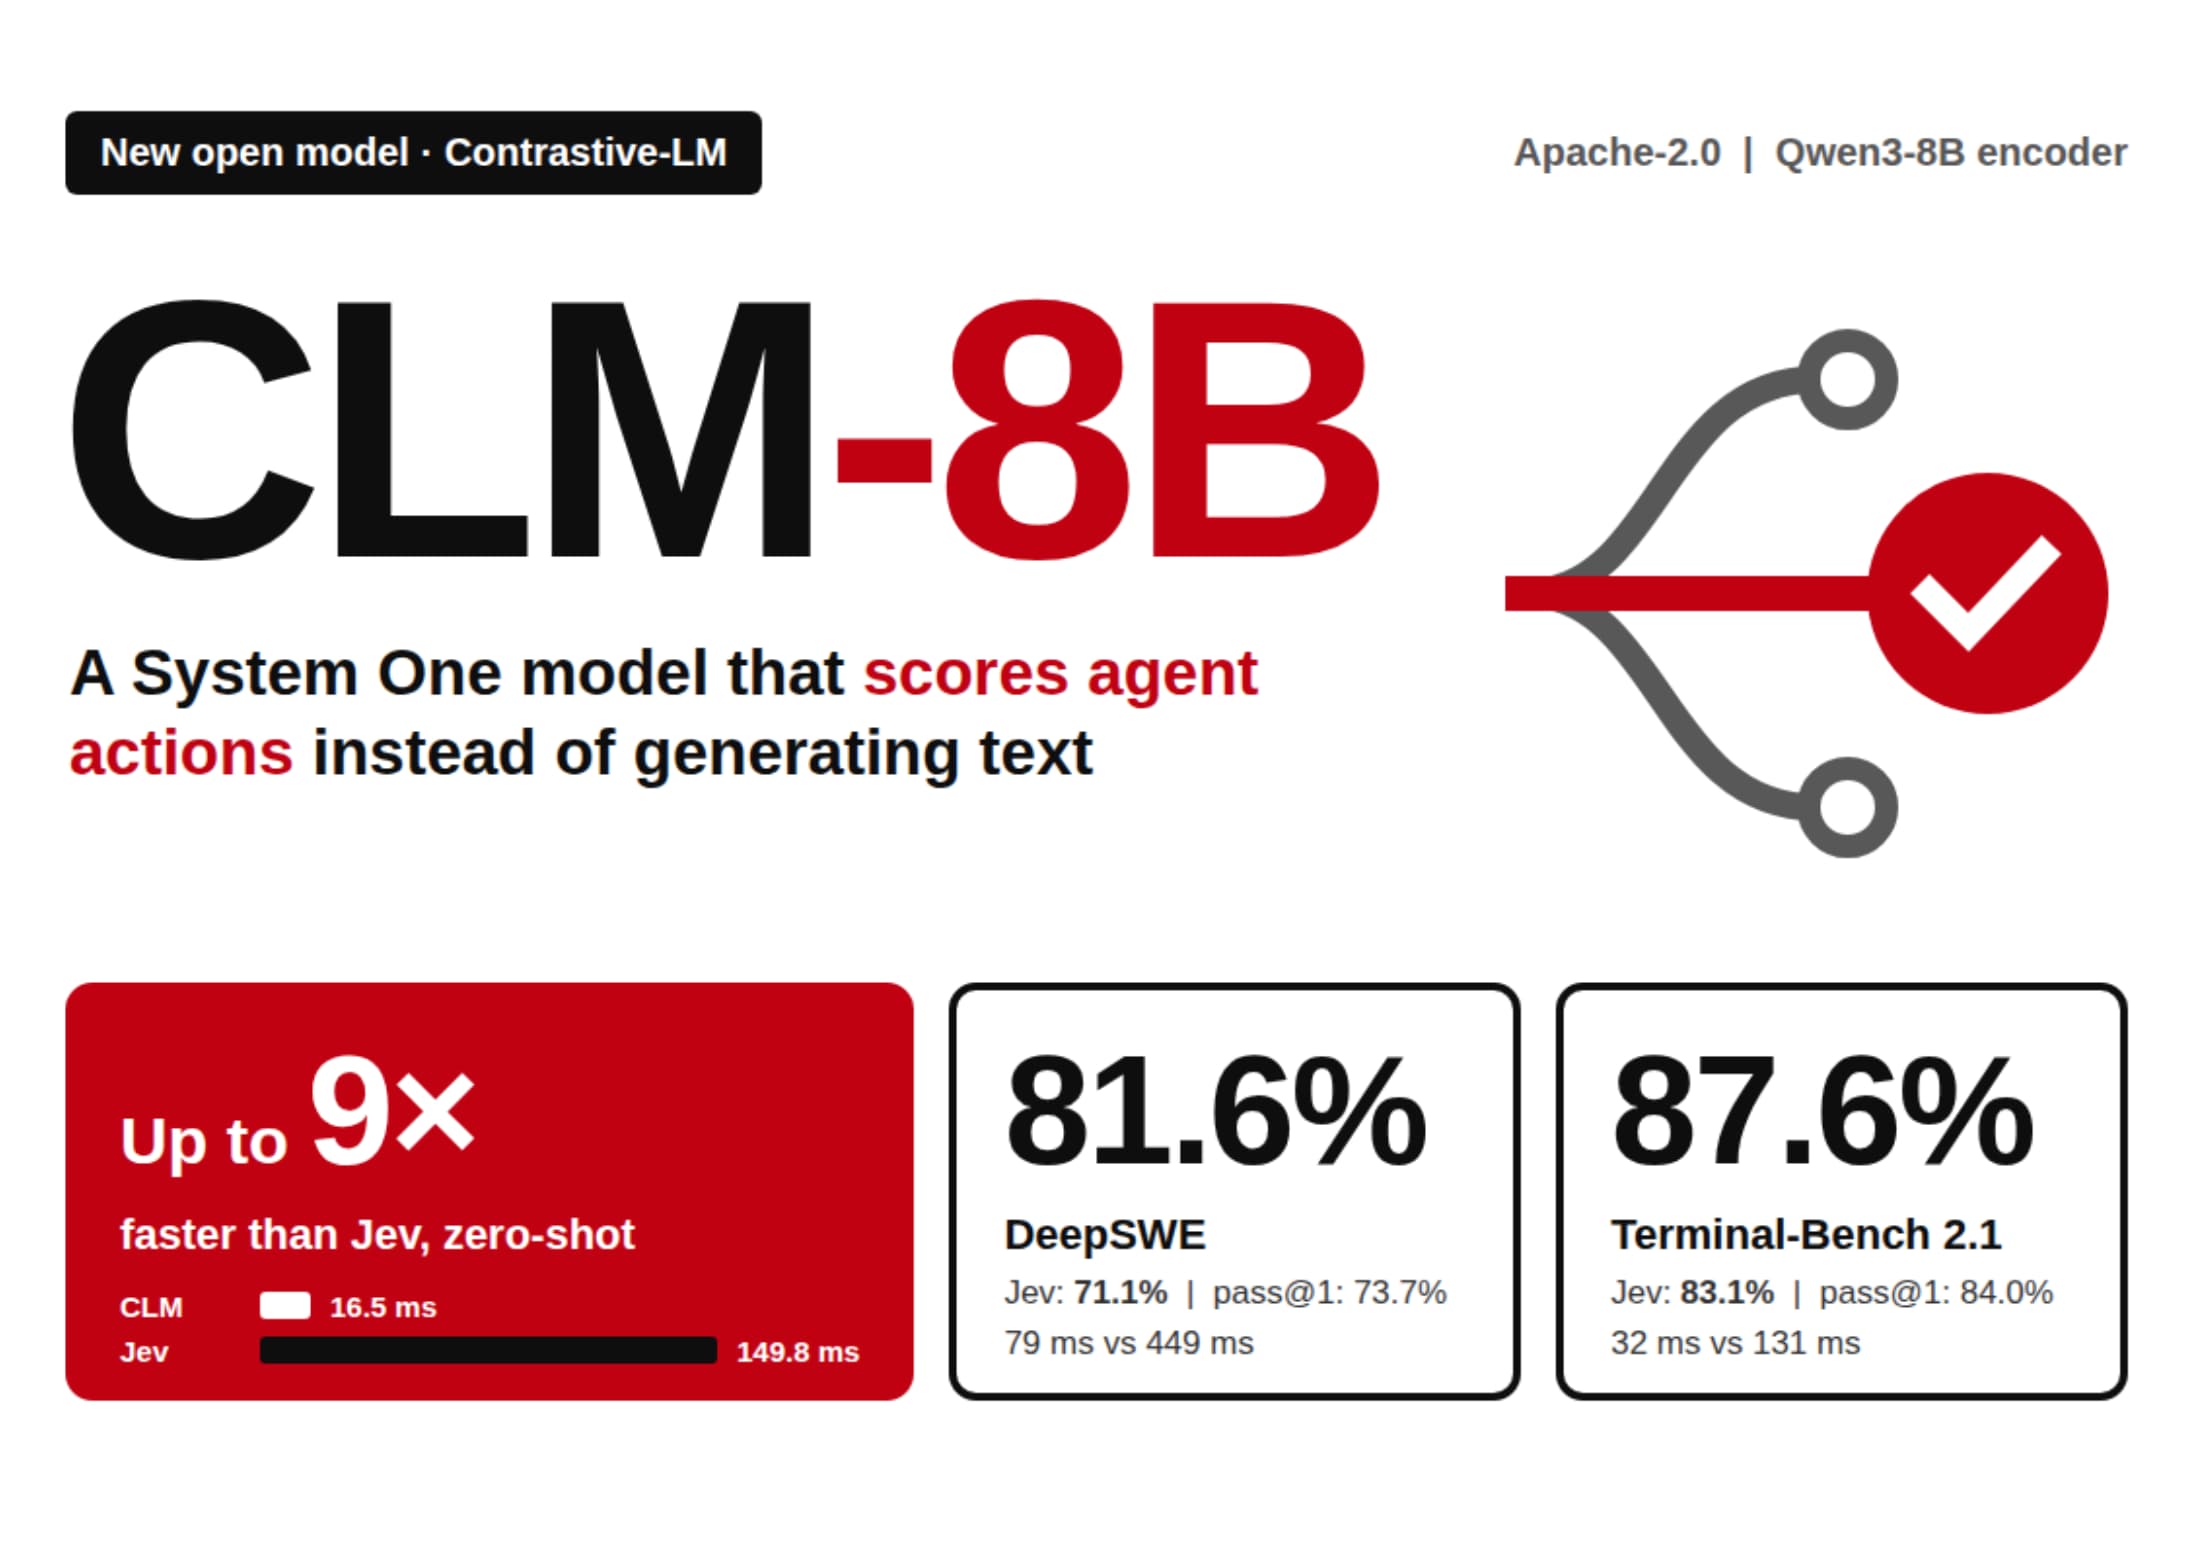
CLM-8B: No Text, Just Decisions
AI modelsSeptember 24, 2026
Anthropic's Sonnet 5.5: 7x Coding Leap
AI modelsSeptember 28, 2026
Anthropic Cuts Prices, Raises the Bar
AI modelsSeptember 22, 2026
ki-daily.
OpenAI Slashes GPT-6 Prices by Half
AI modelsSeptember 22, 2026
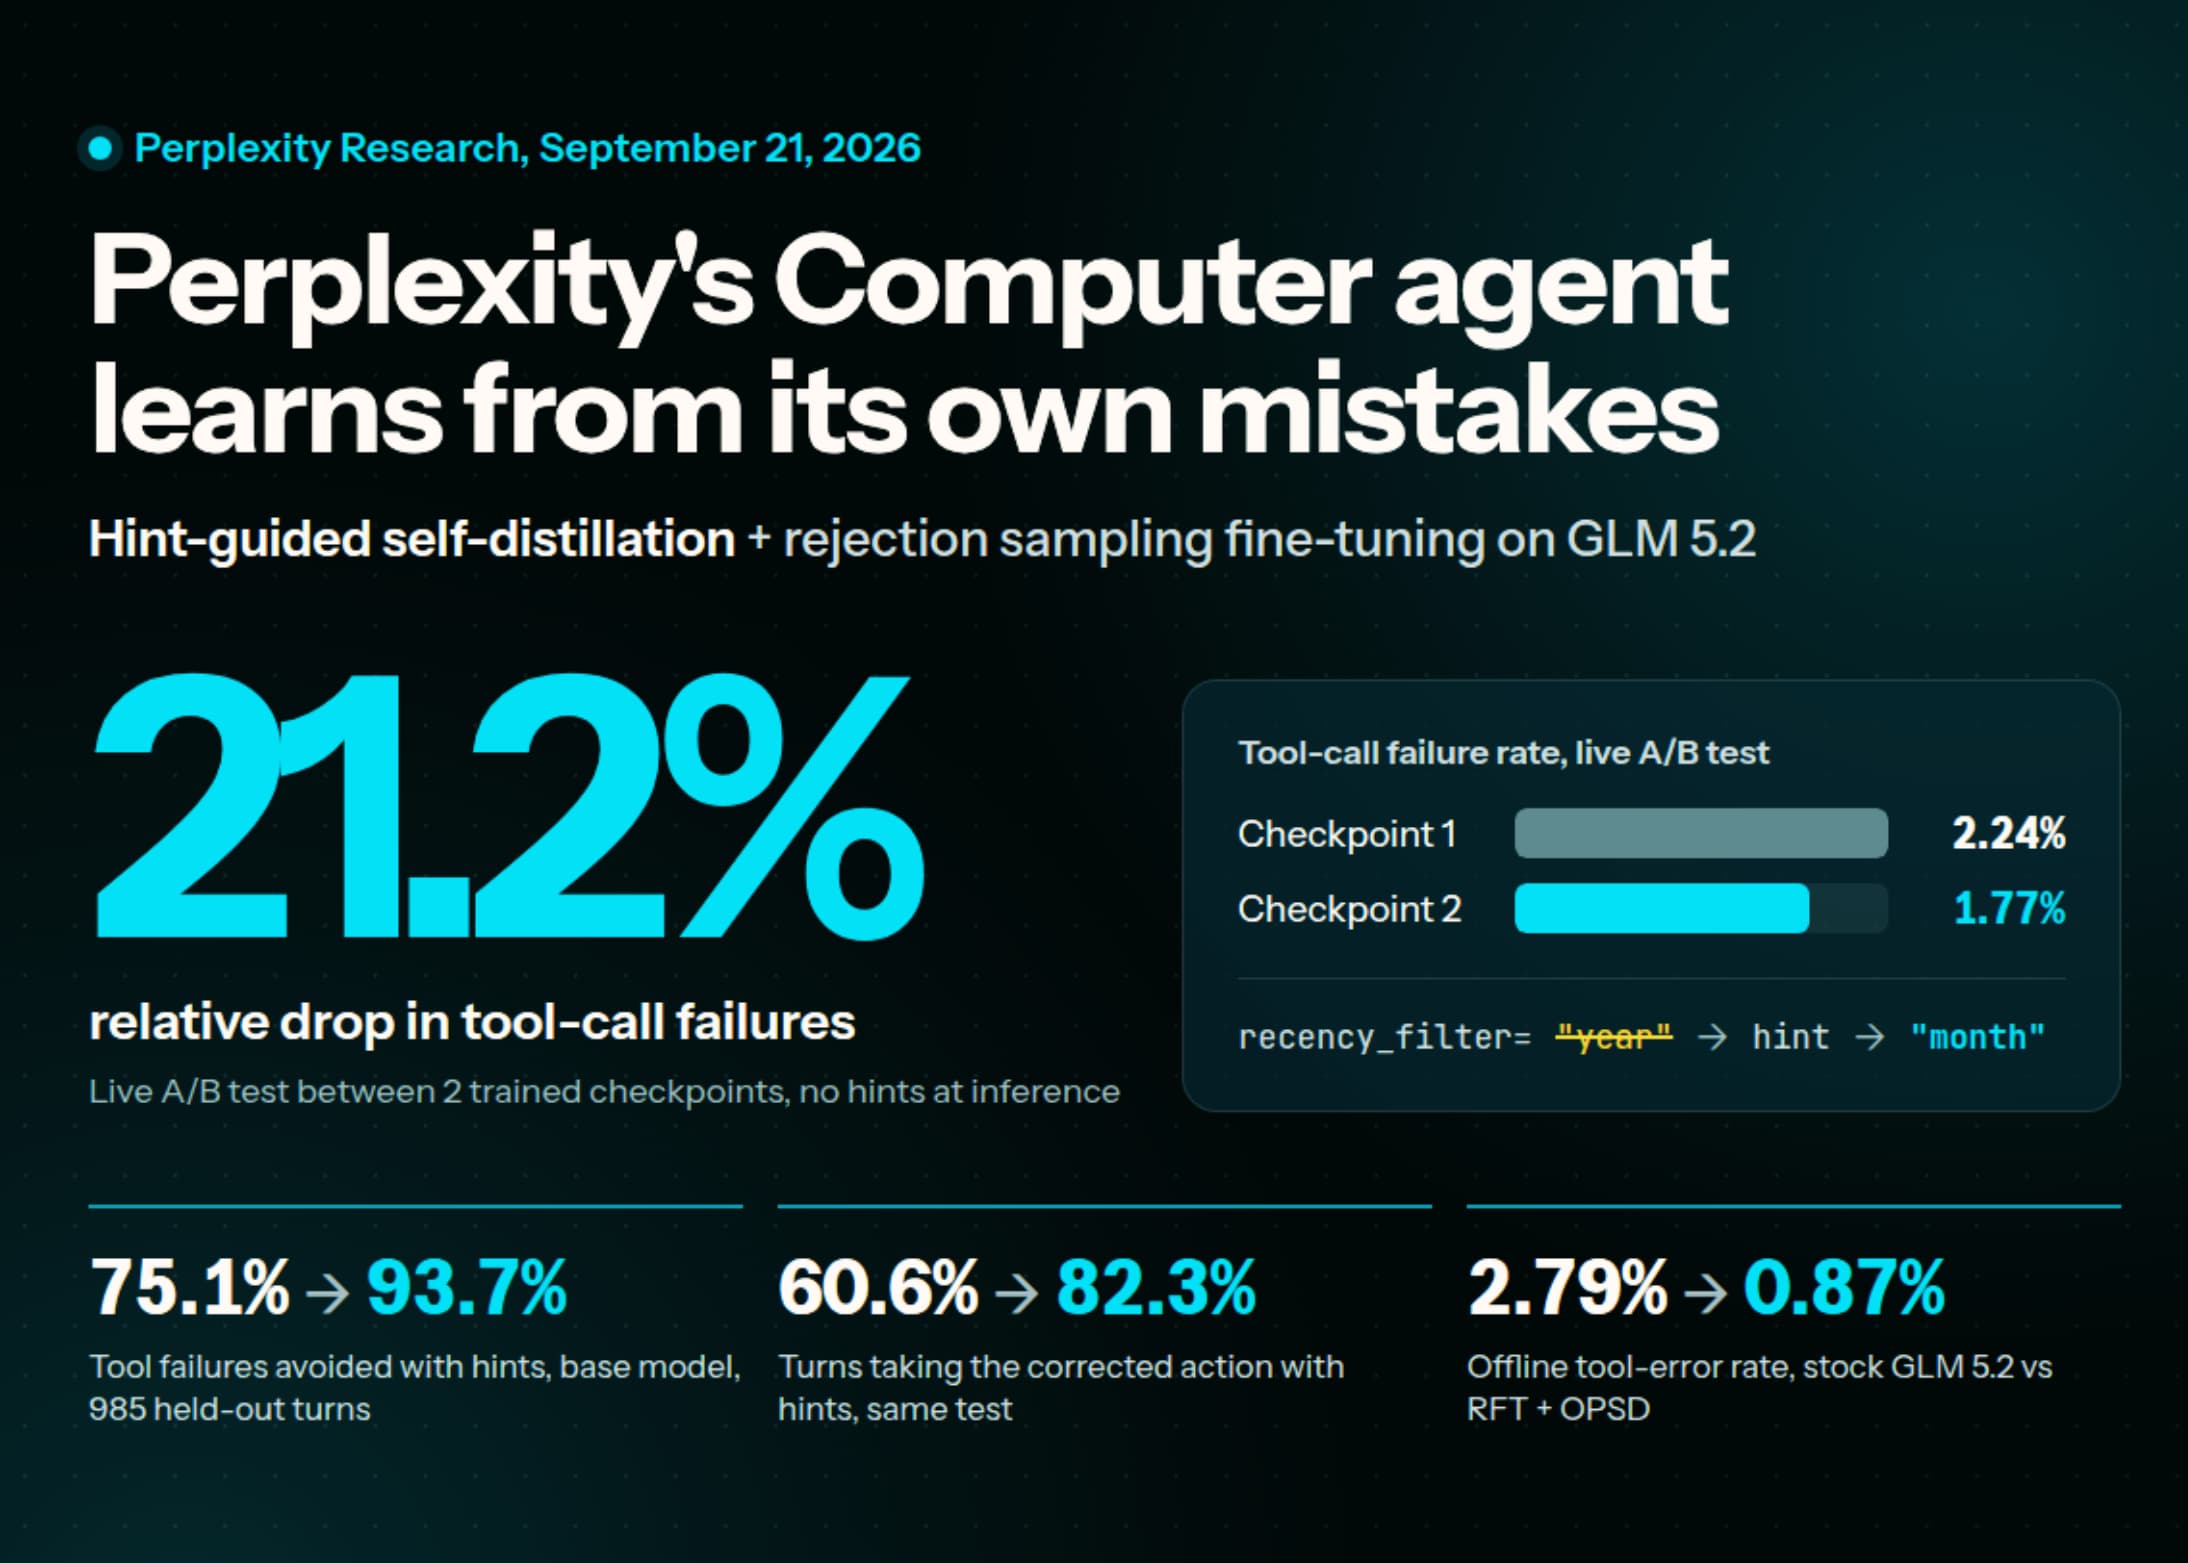
Perplexity Learns From Failures
AI modelsSeptember 25, 2026