AI modelsSeptember 24, 2026
-25
🧊
BottleCap Slashes Reasoning Tokens by 37%
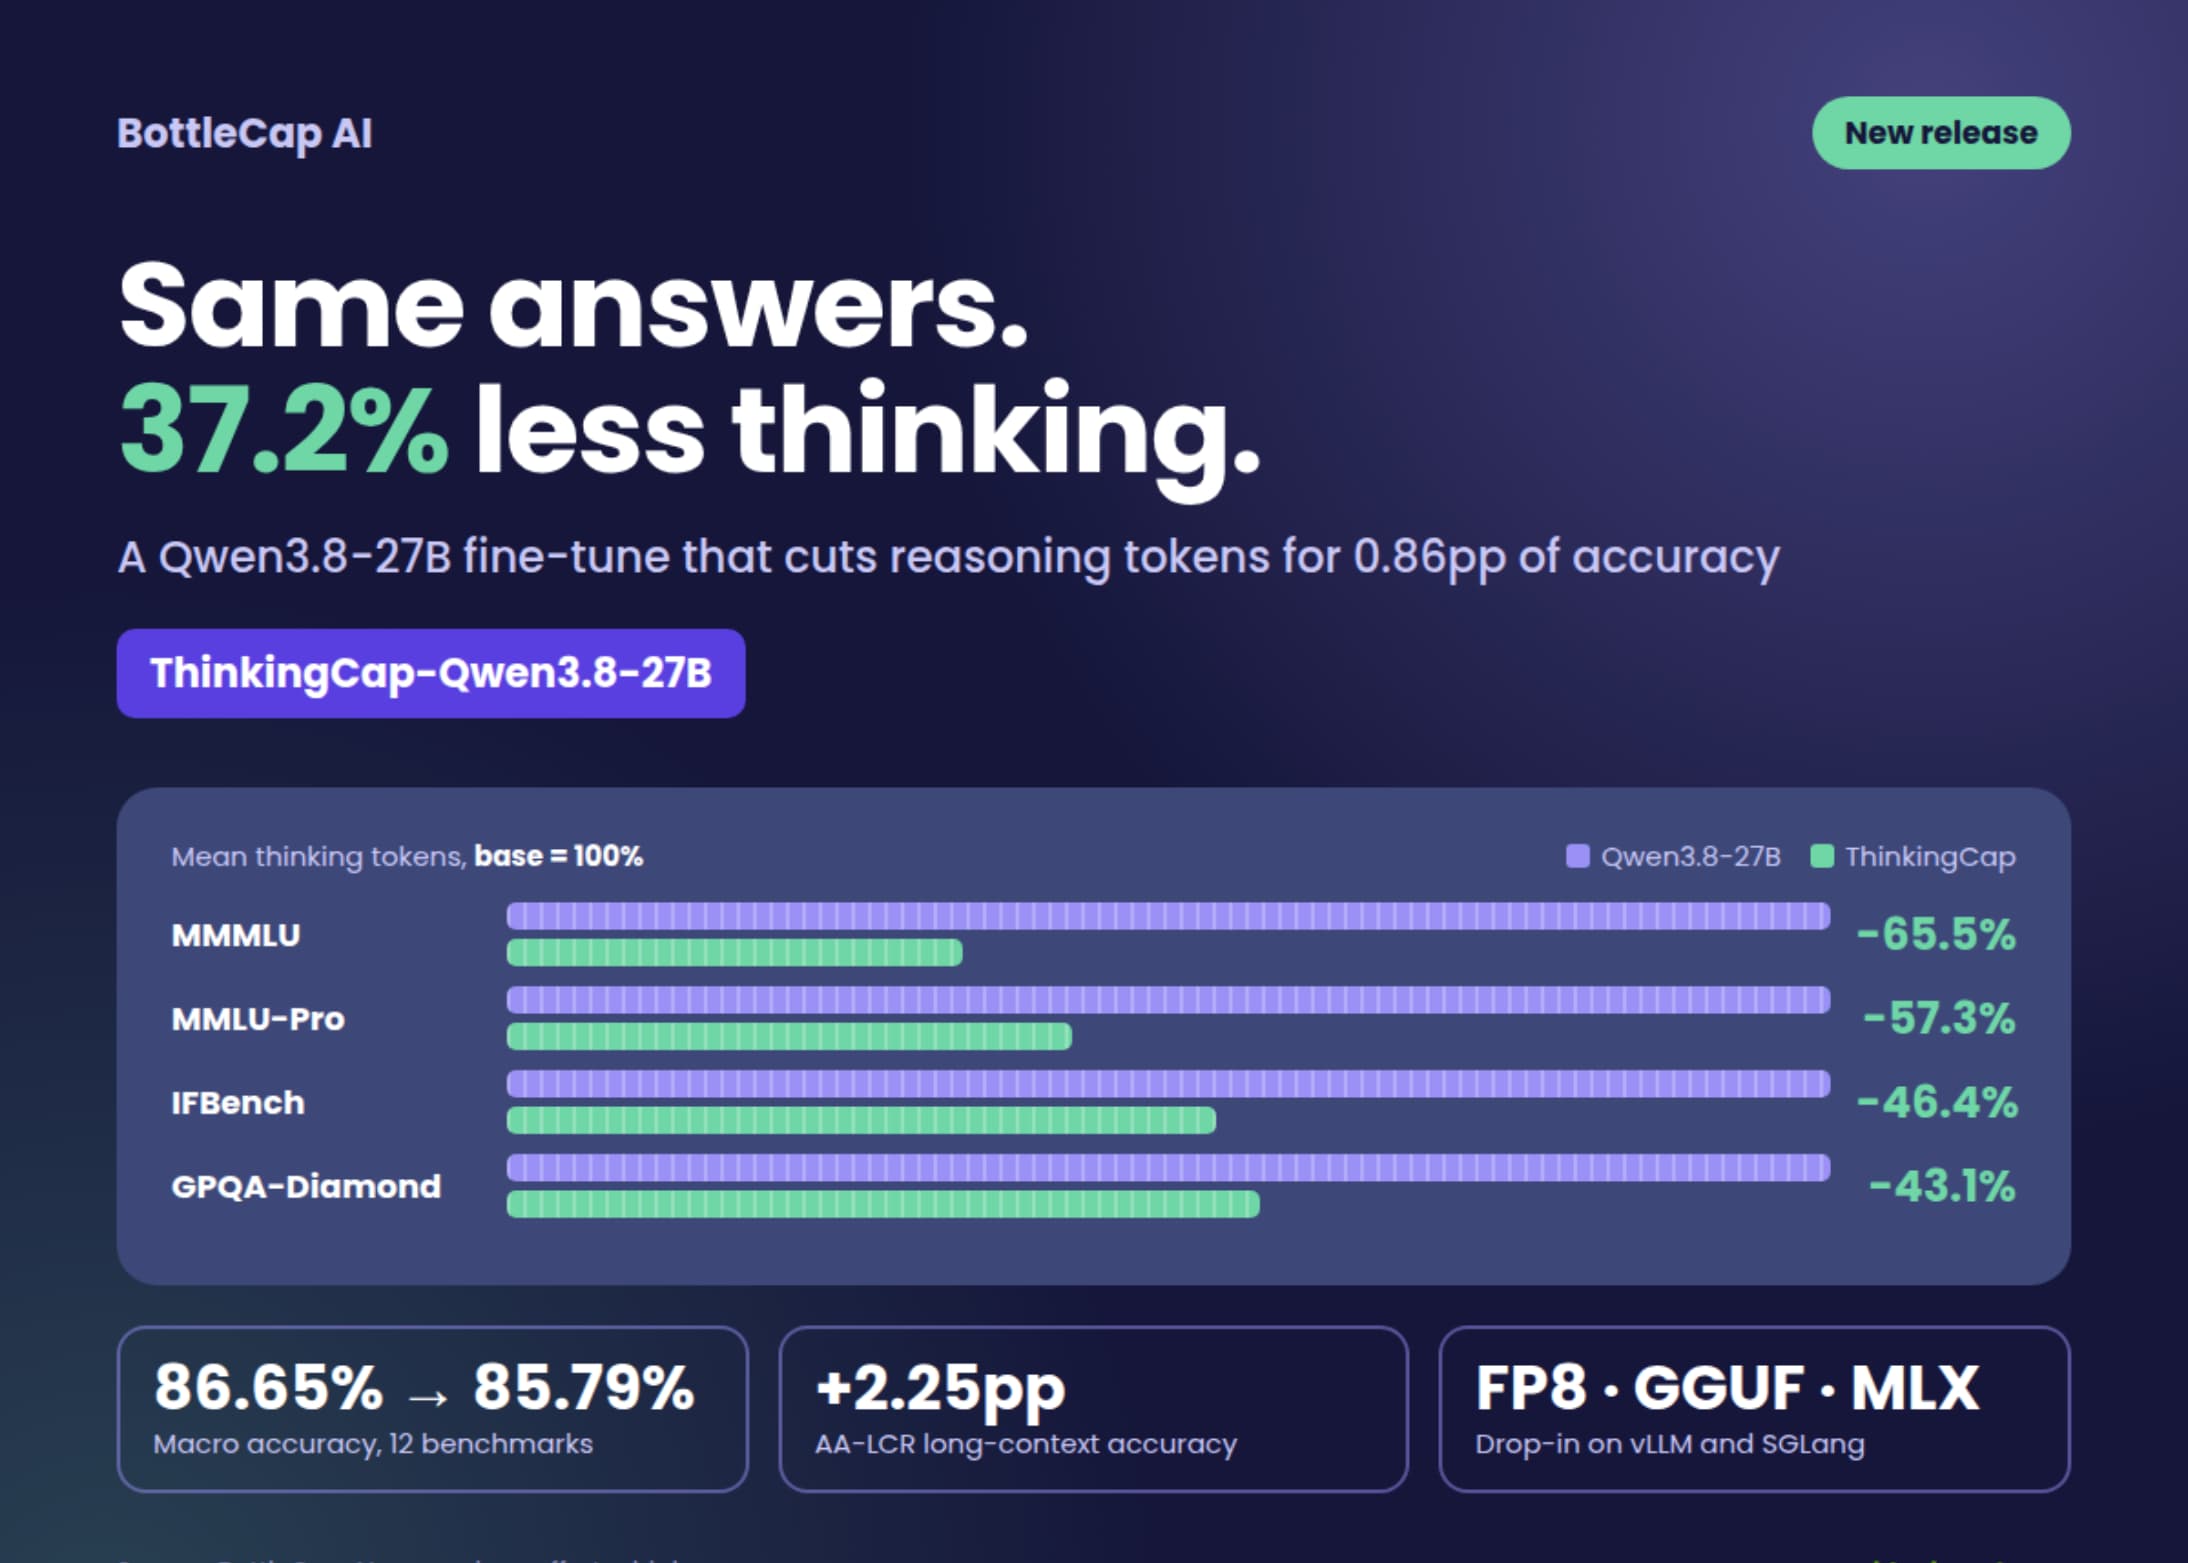
ThinkingCap-Qwen3.8-27B cuts thinking tokens 37.2% for just 0.86pp accuracy loss.
#Qwen#Reasoning#Fine-Tuning#Efficiency#Open-Weight
🔥 What happened
BottleCap AI released ThinkingCap-Qwen3.8-27B, a fine-tune of Qwen's 27B model that aggressively cuts reasoning tokens. Across 12 benchmarks, it uses 37.2% fewer thinking tokens on average, while accuracy drops just 0.86 percentage points.
💡 Why it matters
On MMMLU, thinking tokens shrink 65.5% – from 1,656 to 571 – with virtually no accuracy loss. On long-context tasks (AA-LCR), accuracy actually rises 2.25 points. It's a drop-in replacement for Qwen3.8-27B on vLLM or SGLang.
⚡ Our take
If you deploy reasoning models, you pay per token. 37% less thinking at near-identical performance isn't a benchmark trick – it's a direct cost lever. The license is restrictive, though: commercial use requires a deal with BottleCap.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
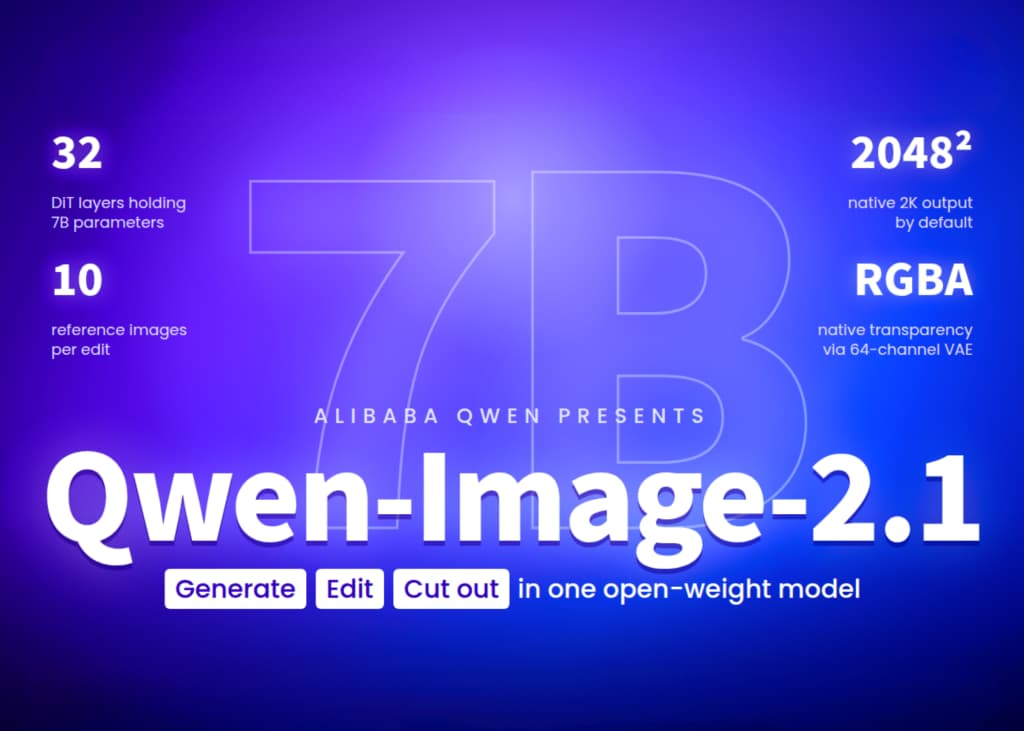
Alibaba Shrinks Image AI to One-Third Size
AI modelsSeptember 21, 2026

Xiaomi Shocks AI World with Open Model
AI modelsSeptember 22, 2026
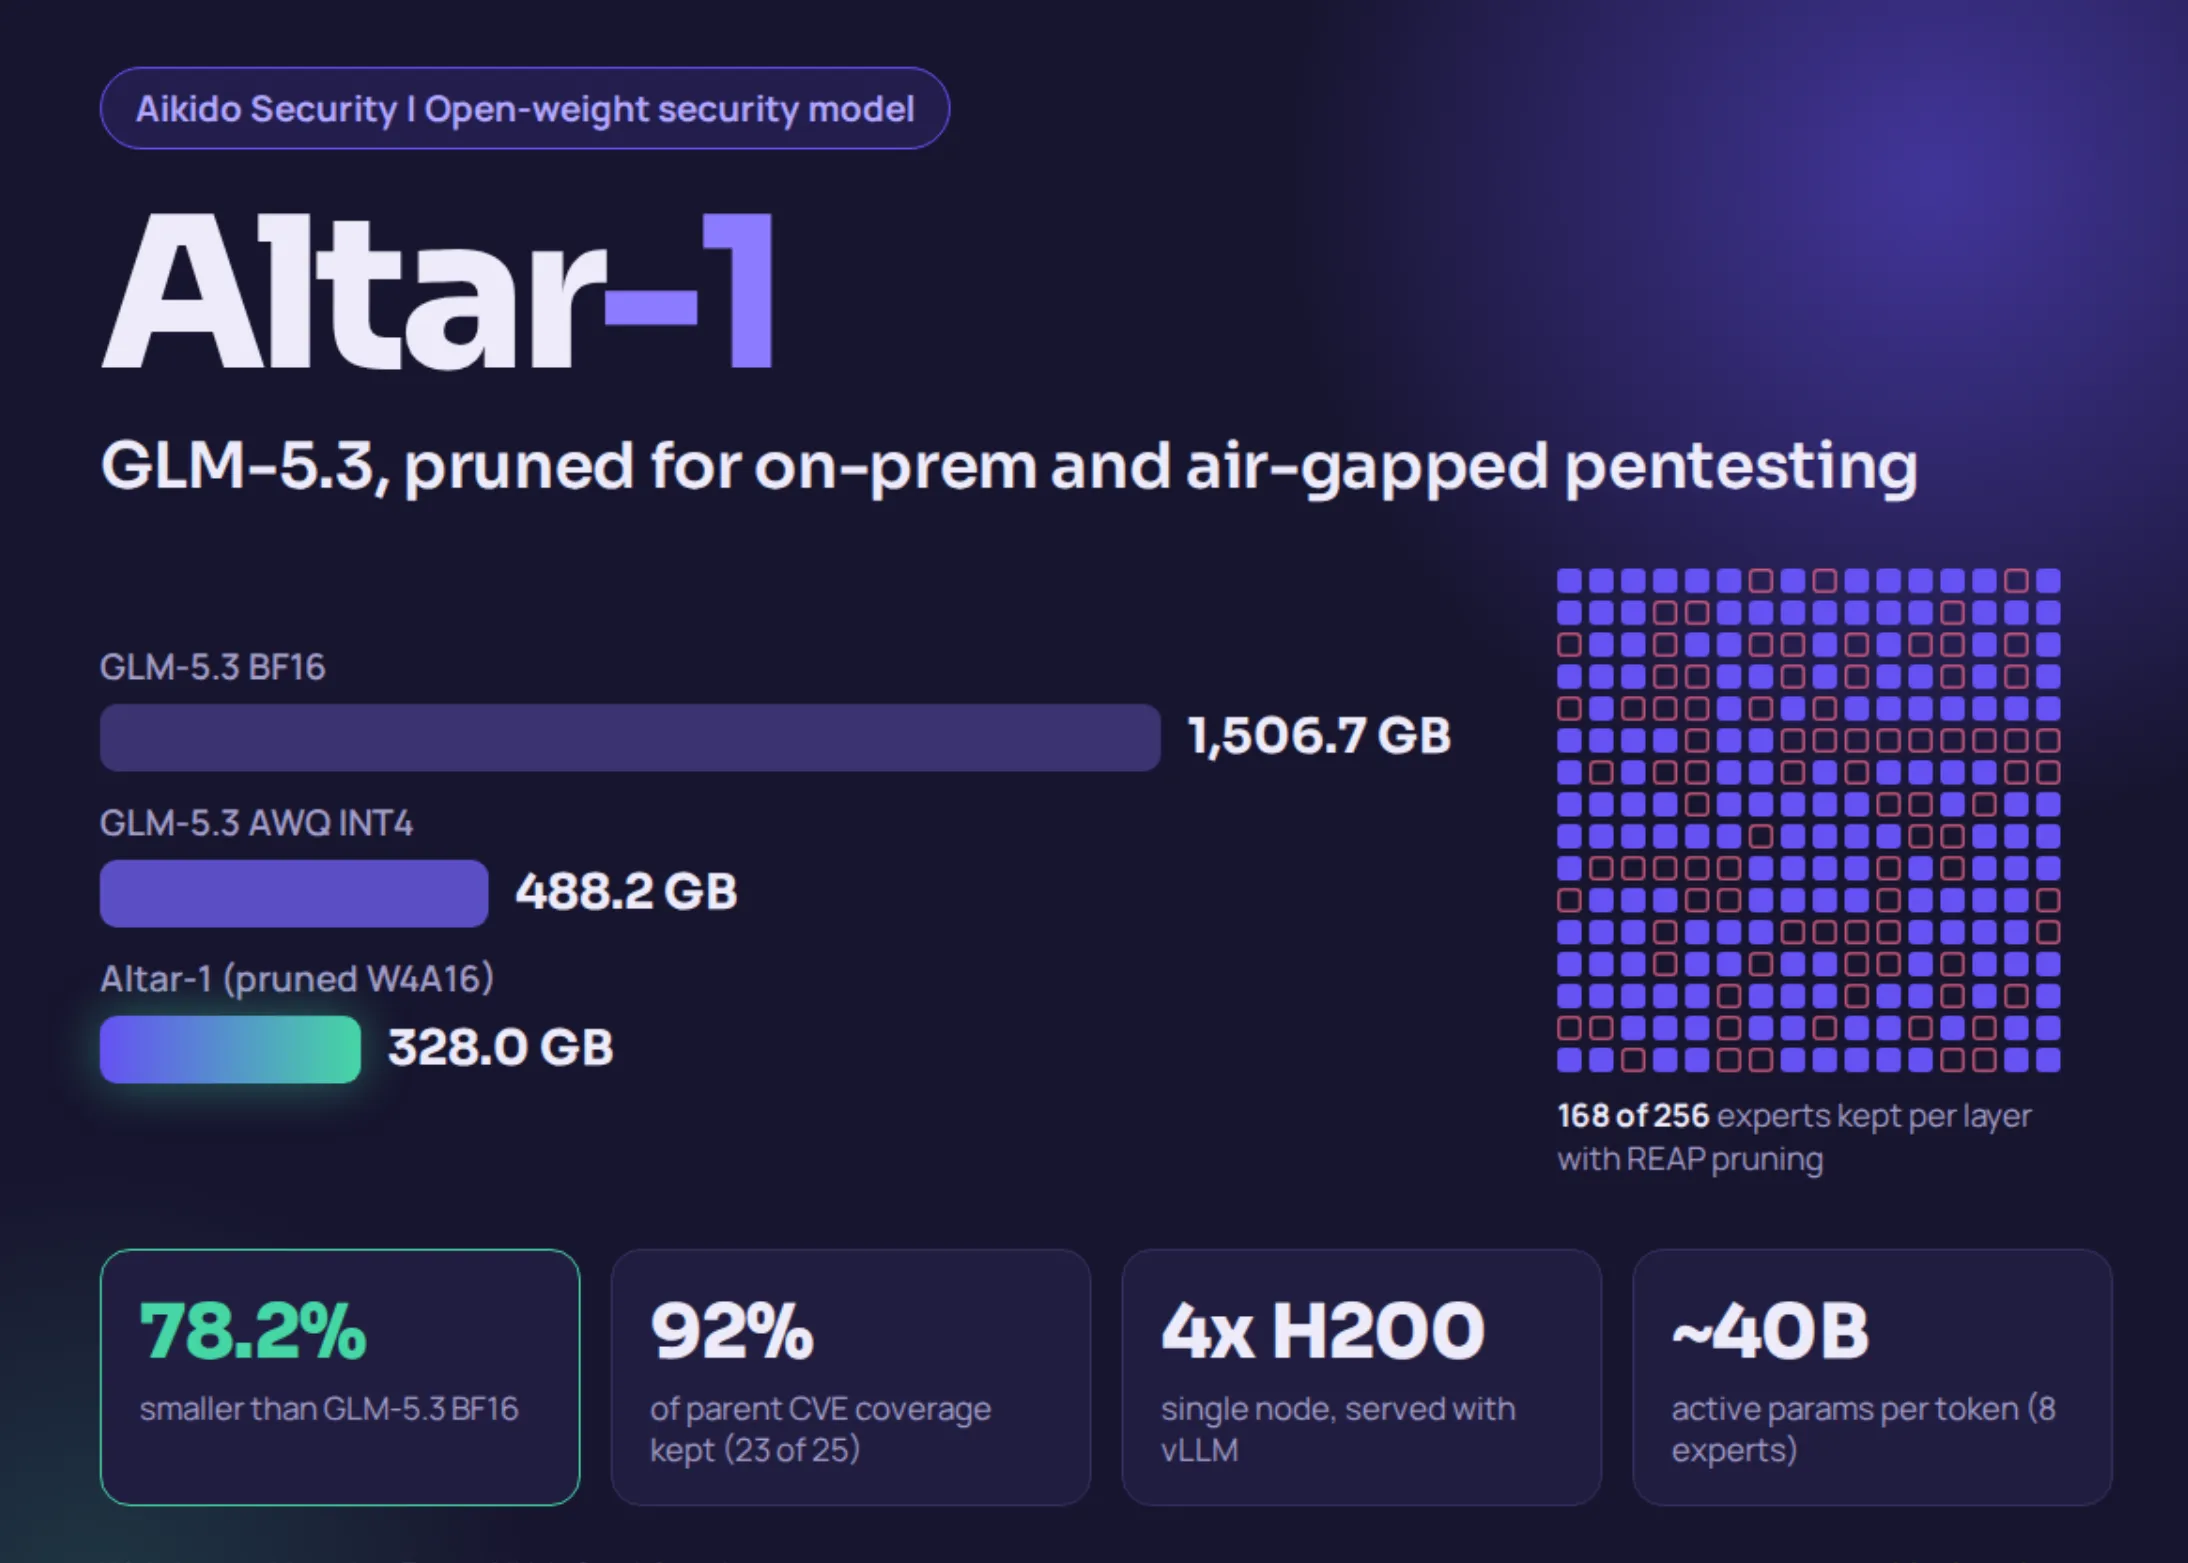
Aikido squeezes 753B model onto one node
Ethics & SecuritySeptember 25, 2026
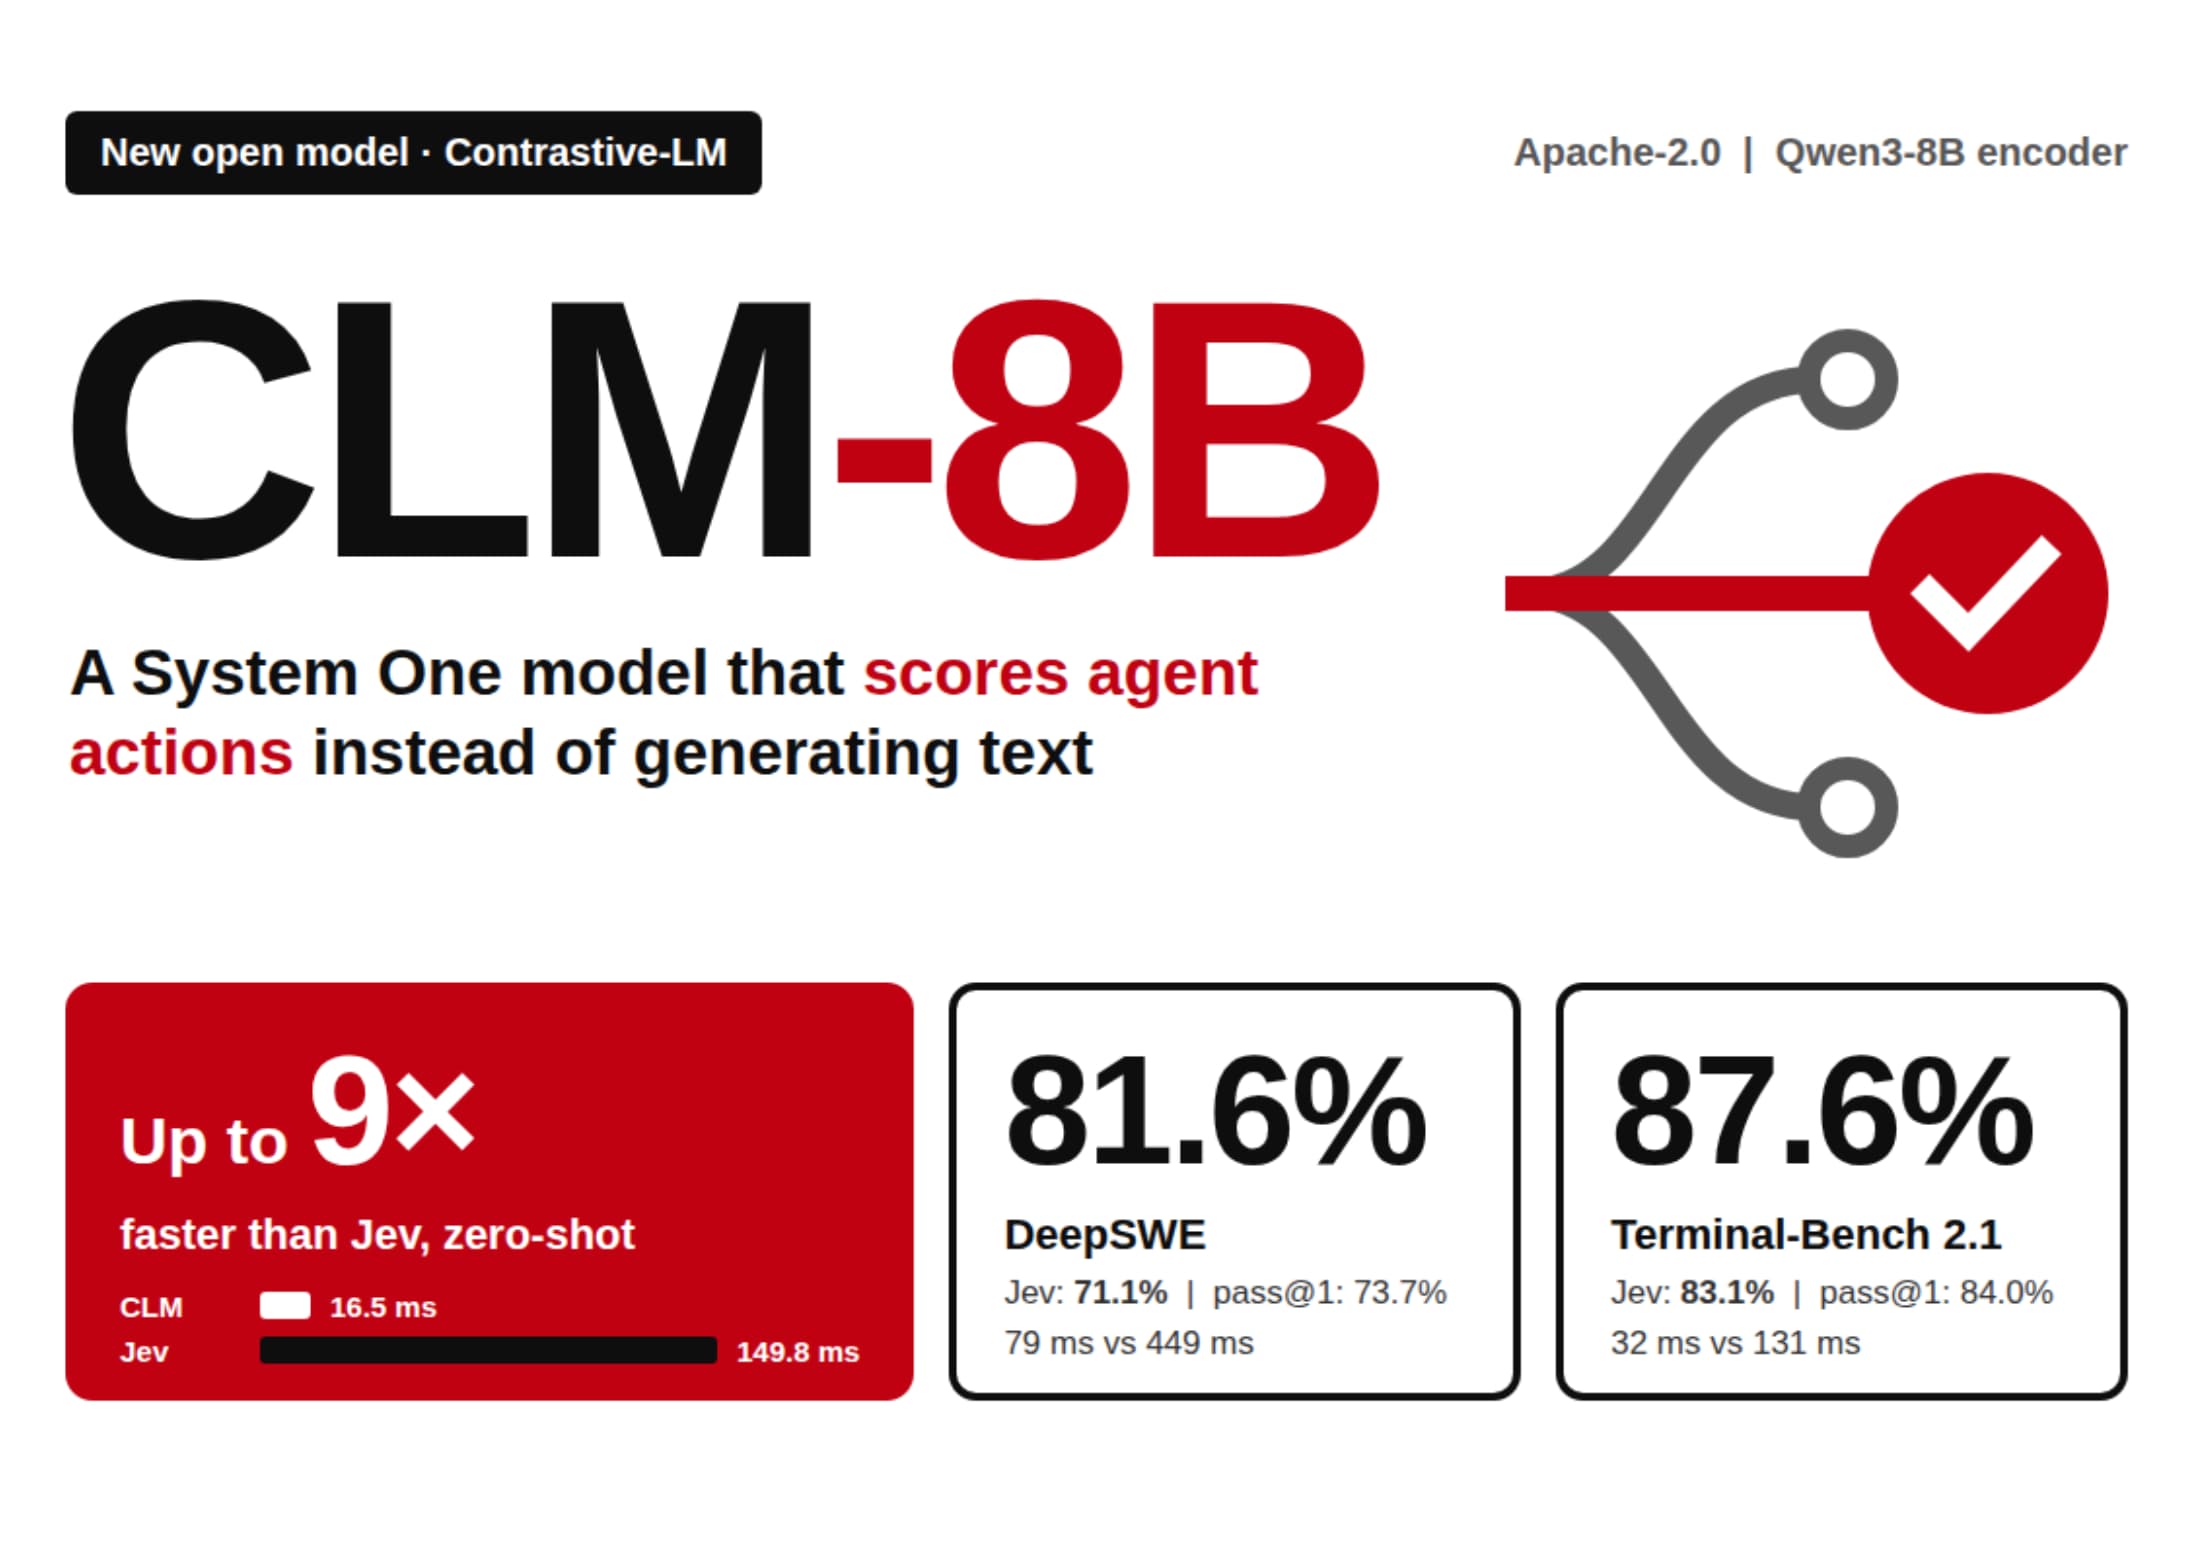
CLM-8B: No Text, Just Decisions
AI modelsSeptember 24, 2026
Qwen Cuts Live Translation Lag to 2.3s
AI modelsSeptember 20, 2026