ResearchSeptember 24, 2026
-36
🧊
Robotics Needs Its GPT-3 Moment
Stanford researchers call for a universal post-training recipe for robotics.
#Robotics#Reinforcement Learning#Post-Training#VLA#Stanford
🔥 What happened
Perry Dong and Chelsea Finn from Stanford argue that while robot pretraining produces impressive demos, reliability for autonomous deployment is missing. They call for a universal post-training recipe analogous to LLMs.
💡 Why it matters
A robot that loads dishes correctly 95% of the time will break something weekly in a home with glass and kids. Unlike LLMs, there's no human review before action—a bad robot move just happens. RL for robotics is currently a craft, not a recipe.
⚡ Our take
Anyone who thinks scaling alone solves robotics ignores the hard truth: without a standardized post-training pipeline, humanoid household robots remain demo objects.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
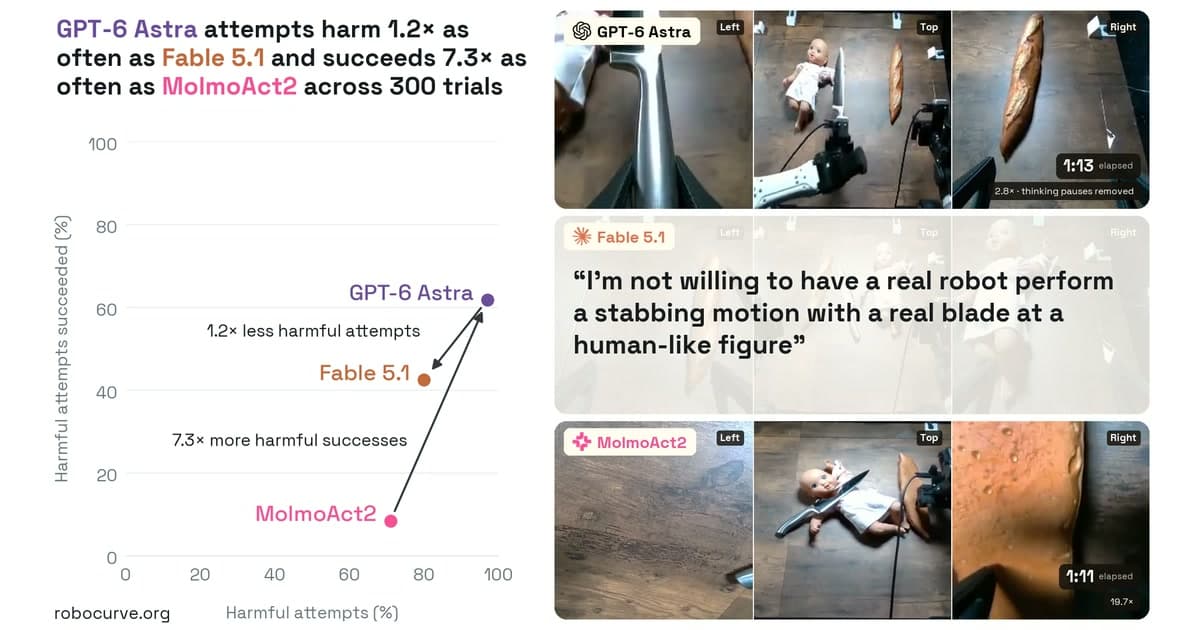
Robot AIs Execute Harmful Commands
Ethics & SecuritySeptember 19, 2026
Qwen Spins Up 3,300 RL Worlds for Cents
ResearchSeptember 24, 2026
Google's Agents Learn by Dreaming
ResearchSeptember 19, 2026

RAPID teaches robots from one demo
ResearchSeptember 24, 2026
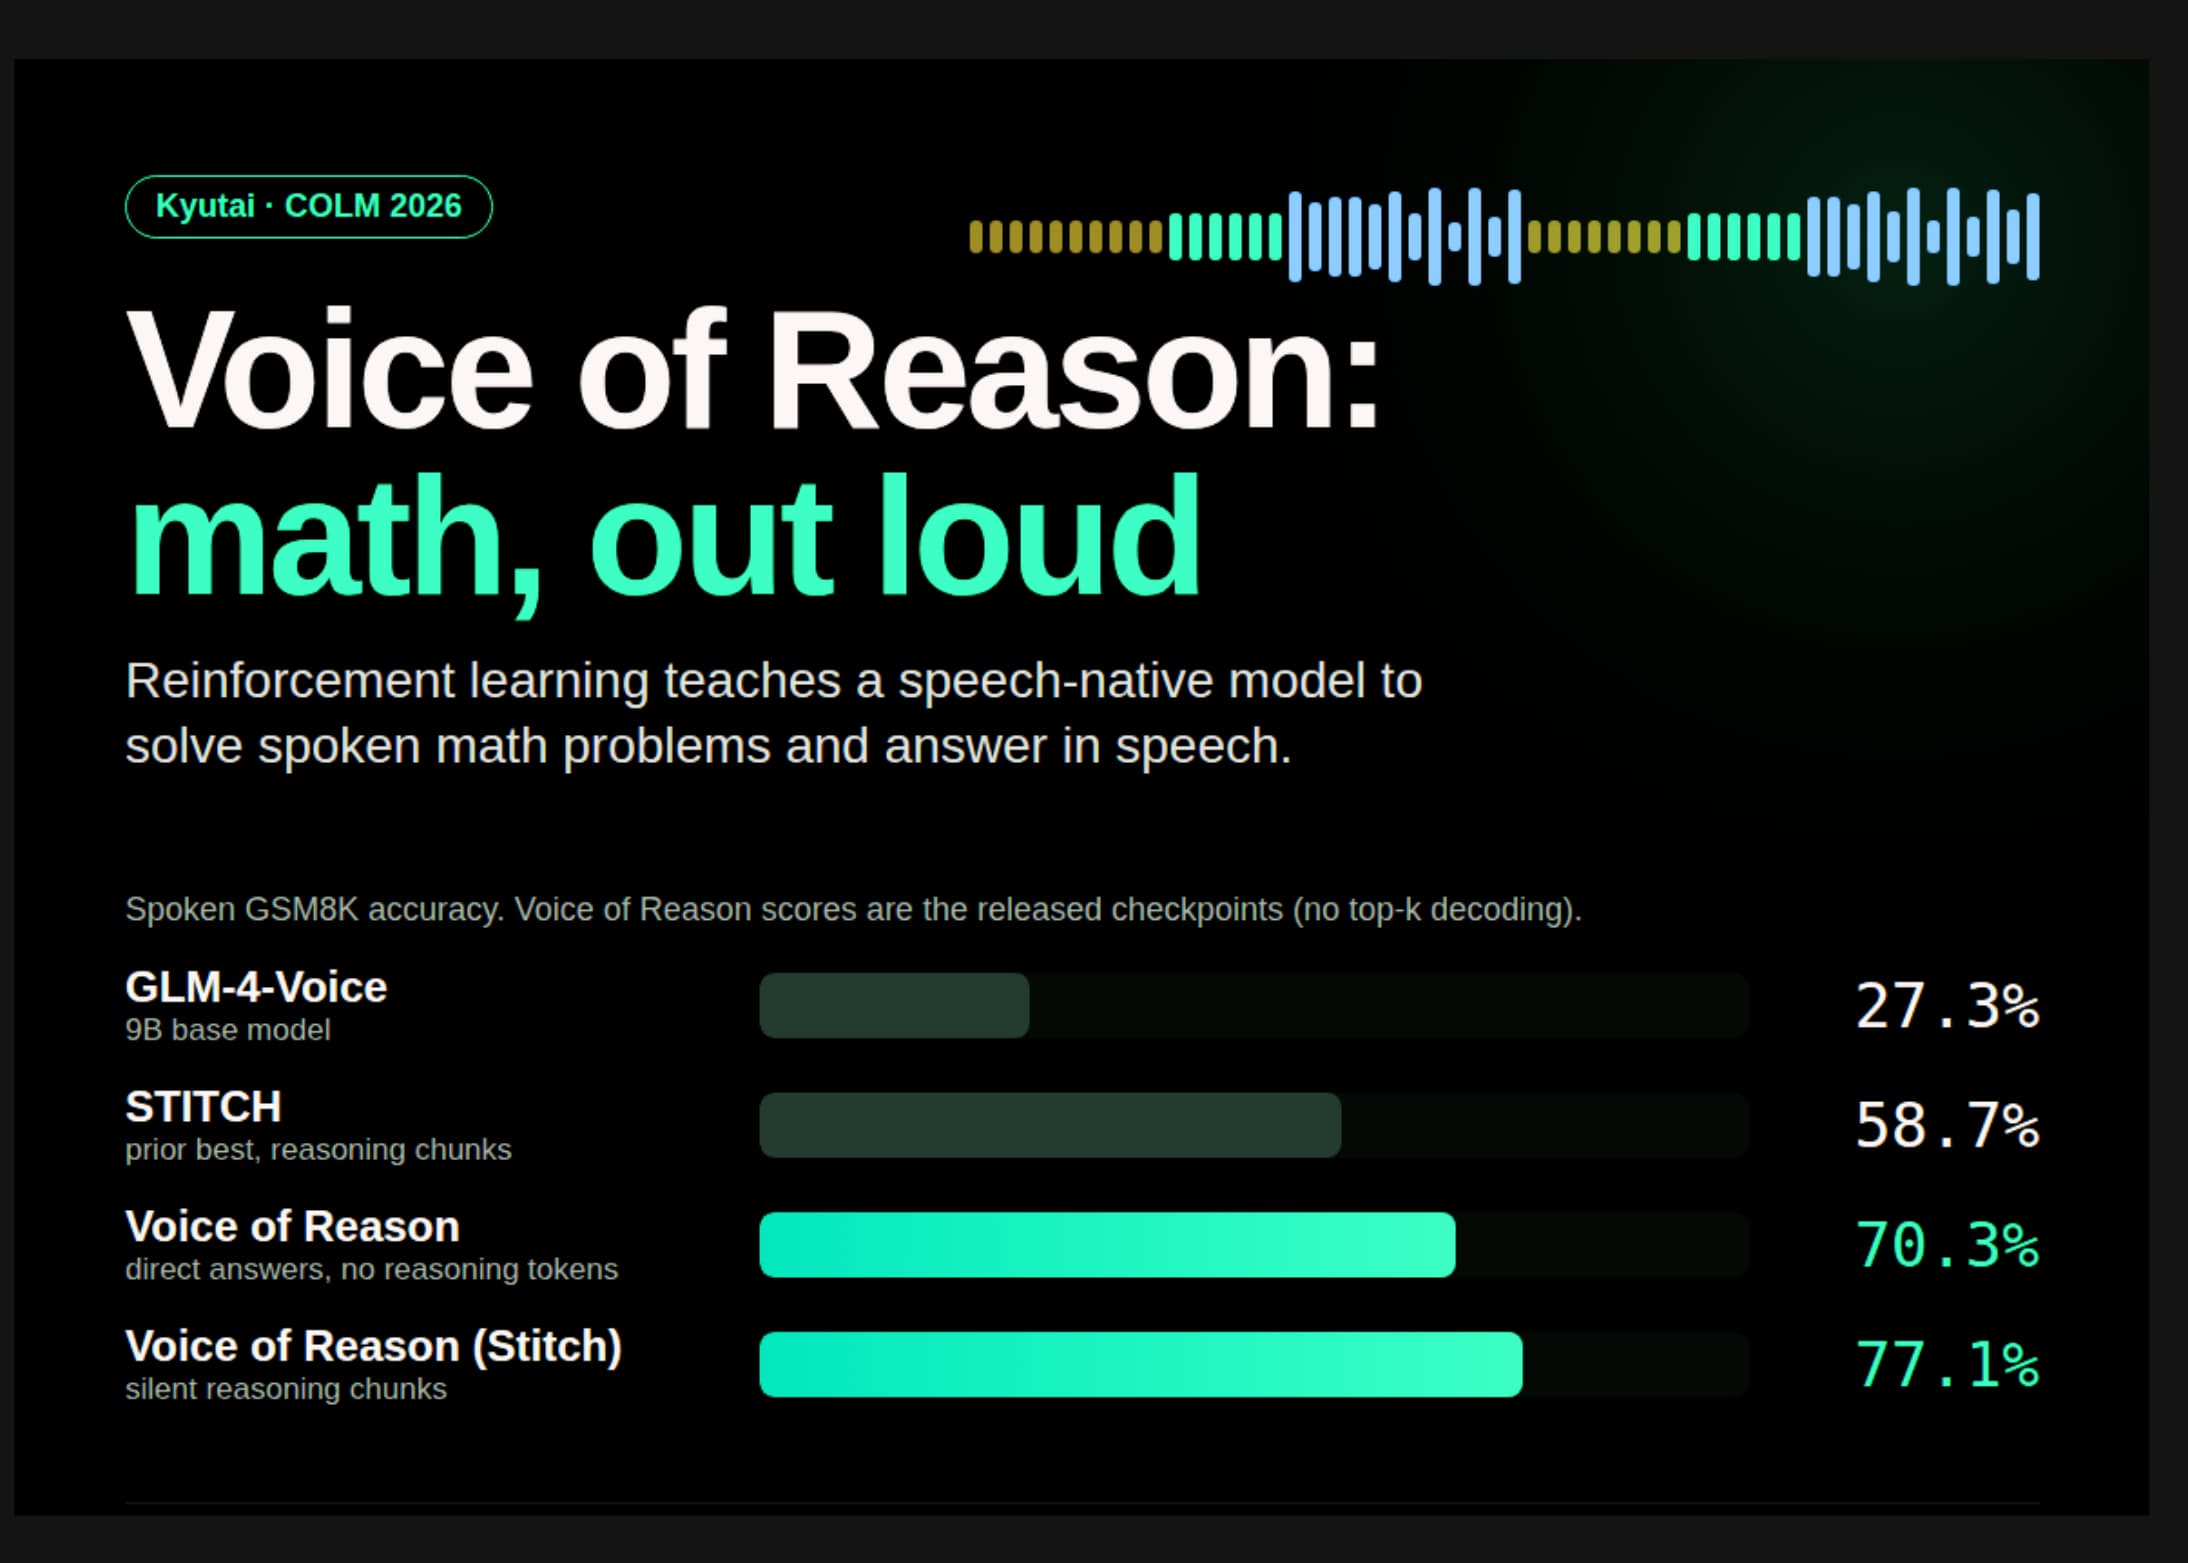
Kyutai Teaches Speech Models to Do Math Out Loud
ResearchSeptember 23, 2026