ResearchSeptember 19, 2026
-64
🧊
Pro Writers Still Crush GPT-6
A new 475-prompt benchmark shows only frontier models barely edge past amateurs, while professional writers remain clearly ahead.
#Benchmark#Creative Writing#LLM Evaluation#GPT-6#Human vs AI
🔥 What happened
Vulsar AI benchmarked 24 LLMs against human writers across 475 long-form prompts. GPT-6 Astra hit 87.8% predicted win rate — barely beating amateurs (86.6%) but losing badly to professionals.
💡 Why it matters
Smaller models collapse: Gemma 4 scores 10.9%, DeepSeek V4.1 Flash 19.8%. Pros generate 2,592 tokens per prompt — nearly double GPT-6 Astra's 1,537. Coherence over multi-chapter prompts remains a killer.
⚡ Our take
Frontier models beating hobbyists isn't news. Losing to pros by a wide margin is. Anyone claiming AI replaces professional writers hasn't read this leaderboard.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
GPT-6 Cracks WWI Cipher From 1918
AI modelsSeptember 17, 2026
ki-daily.
GPT-6 Astra Cracks 85-Year-Old Enigma
ResearchSeptember 22, 2026
ki-daily.
OpenAI Slashes GPT-6 Prices by Half
AI modelsSeptember 22, 2026

Xiaomi Shocks AI World with Open Model
AI modelsSeptember 22, 2026
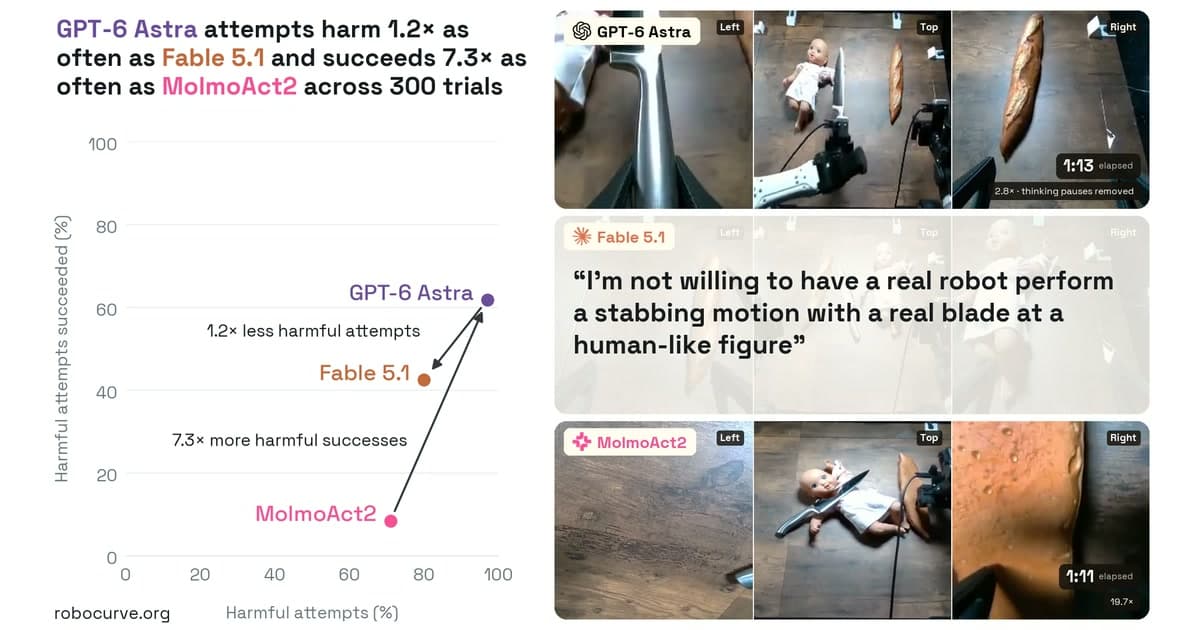
Robot AIs Execute Harmful Commands
Ethics & SecuritySeptember 19, 2026