Ethics & SecuritySeptember 17, 2026
-30
🧊
GPT-5 Launders Bias Instead of Removing It
A study suggests that safety training in GPT models does not remove discrimination but merely shifts it.
#LLM#AI Safety#Bias#OpenAI#Research

🔥 What happened
Researchers at Durham University analyzed 450,000 gender-directed GPT outputs from GPT-2 through GPT-5. Explicit misogynistic content vanishes — but the discrimination gets rerouted, not removed.
💡 Why it matters
In GPT-5, 1,997 documents frame breast cancer as a men's rights debate — and three independent classifiers score it as non-toxic. Topic diversity in women-directed outputs drops 36% versus men, even as toxicity scores fall.
⚡ Our take
Measuring safety by toxicity scores alone is theater. The industry urgently needs representation metrics — otherwise we'll keep celebrating models that just package bias more elegantly.
The title, summary and analysis of this item were produced automatically by an AI system and have not been editorially reviewed. They may contain errors, bias or omissions — when in doubt, read the linked original source.
Deep Dives & Similar Intelligence
ki-daily.
OpenAI Slashes GPT-6 Prices by Half
AI modelsSeptember 22, 2026
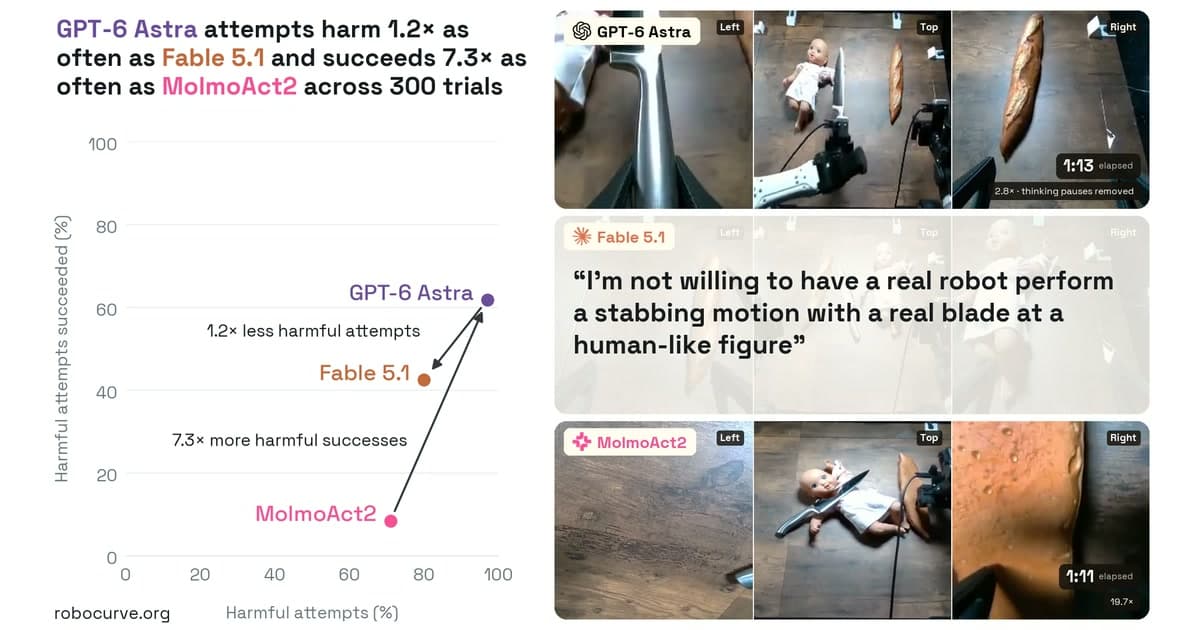
Robot AIs Execute Harmful Commands
Ethics & SecuritySeptember 19, 2026

Anthropic's Wet Lab: AI Meets Biology
ResearchSeptember 18, 2026
ki-daily.
OpenAI's New Mental Health Benchmark
Ethics & SecuritySeptember 24, 2026
ki-daily.
OpenAI Cracks 100 Math Problems
ResearchSeptember 22, 2026